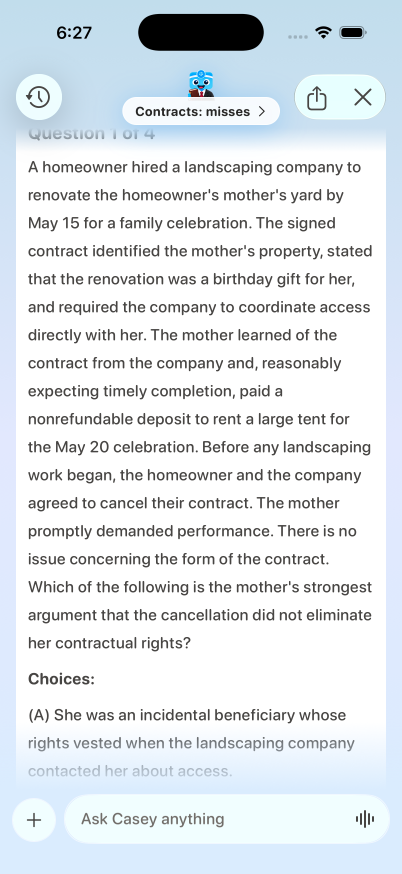
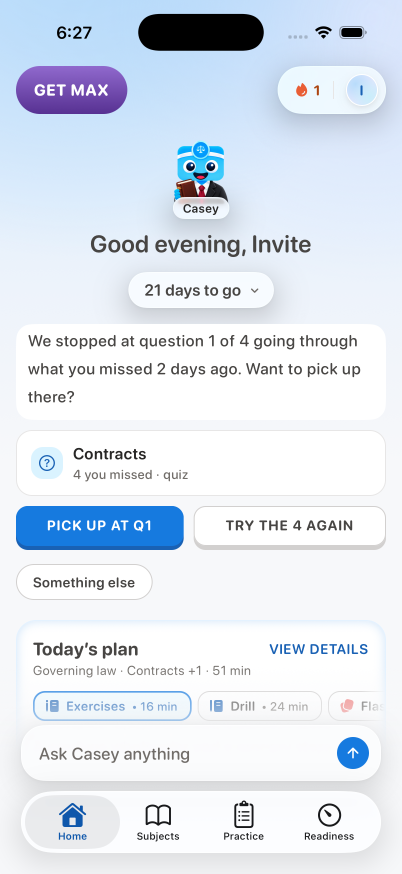
Final version. The prototype stopped after review round 11, at the owner's call: the councils stayed at 7-8 of 10, short of the 9/10 bar, and the next step is a structural change (below), not another fix round.
Prototype · ONC2-8580 · staging data and staging QA accounts only · not shipped · api 9804566b (api#1438), app c1c844b4c (#2659), both draft PRs, not for merge
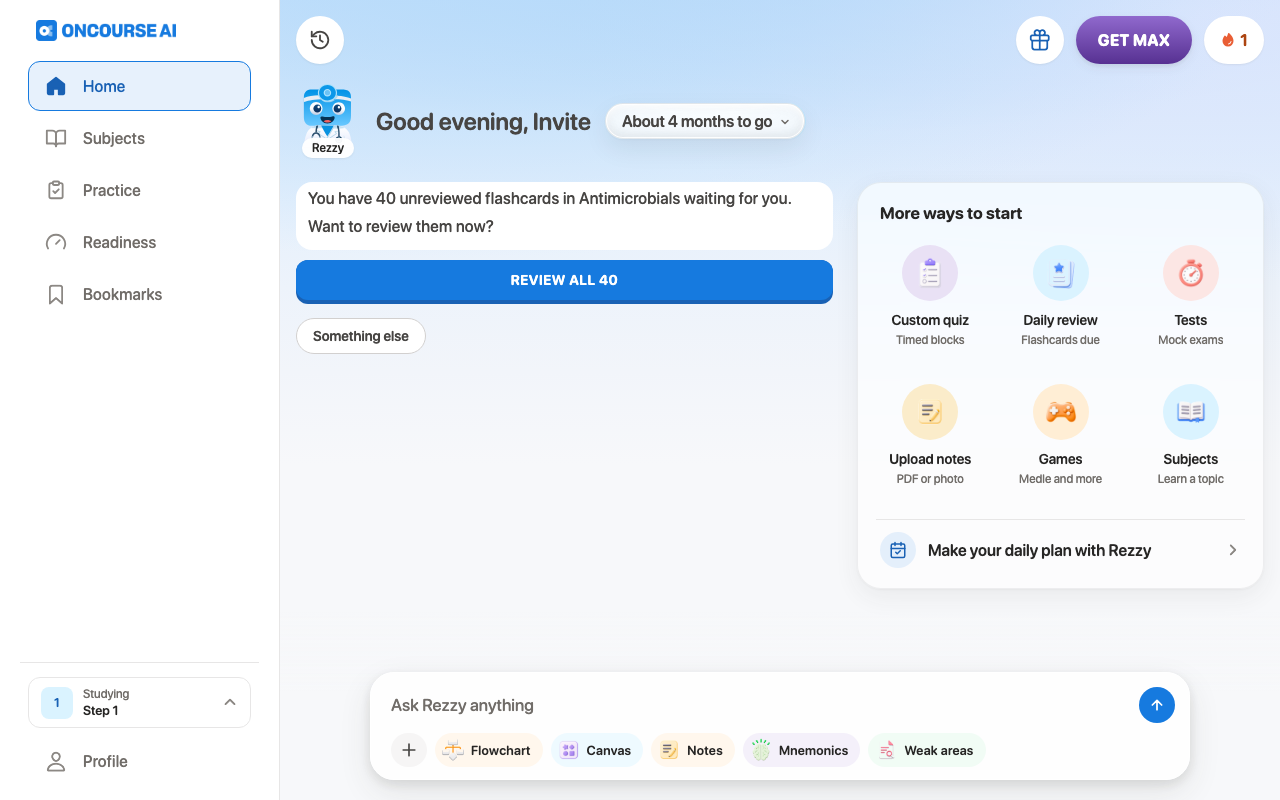
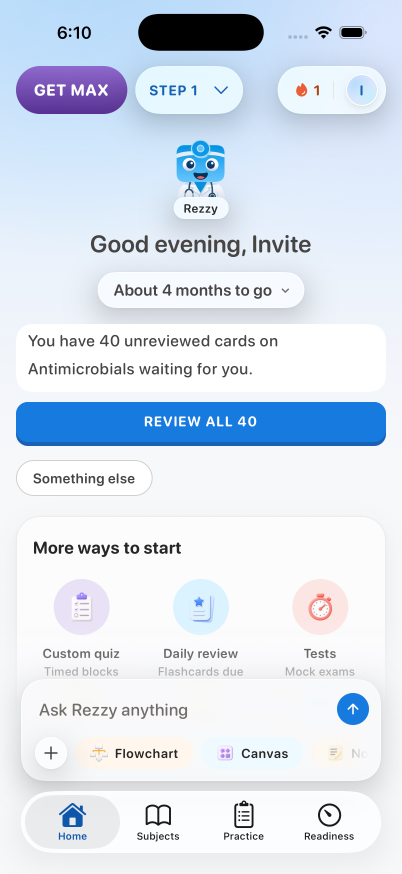
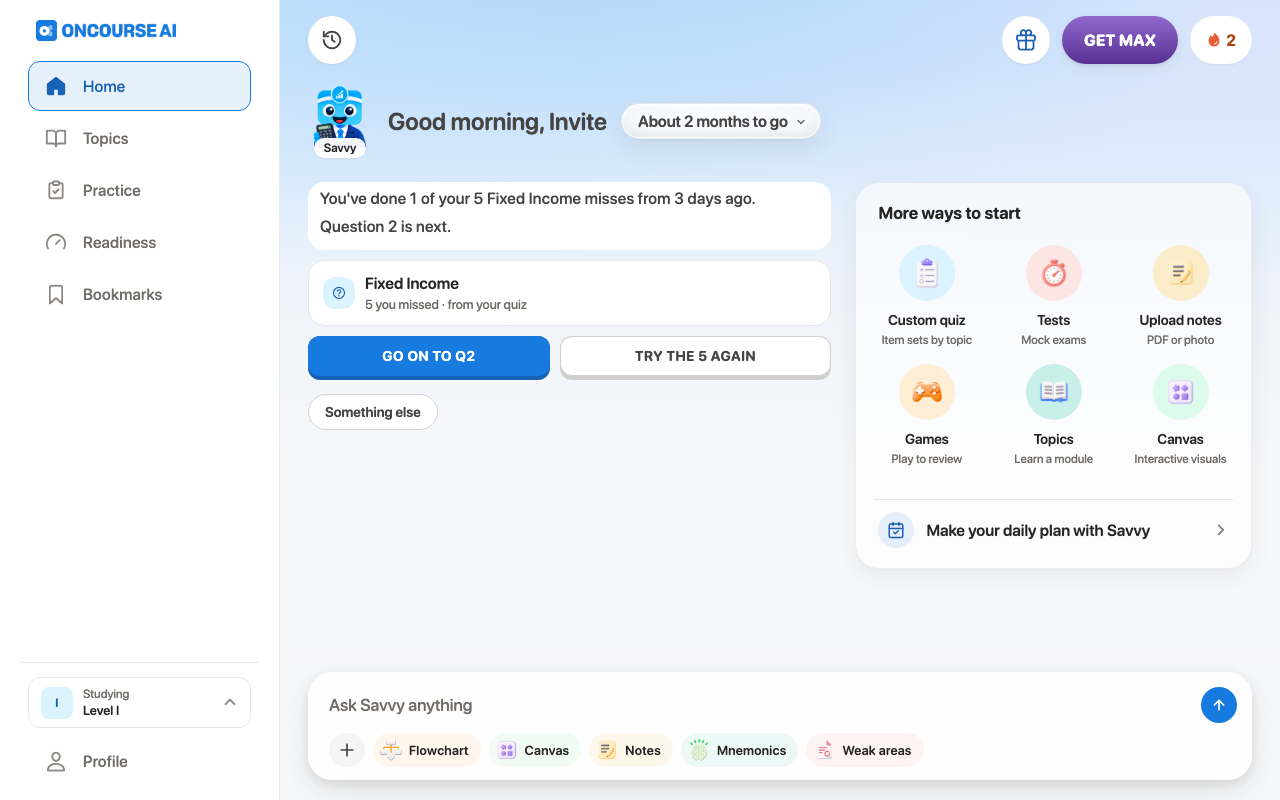
The tutor invites you in, on Home
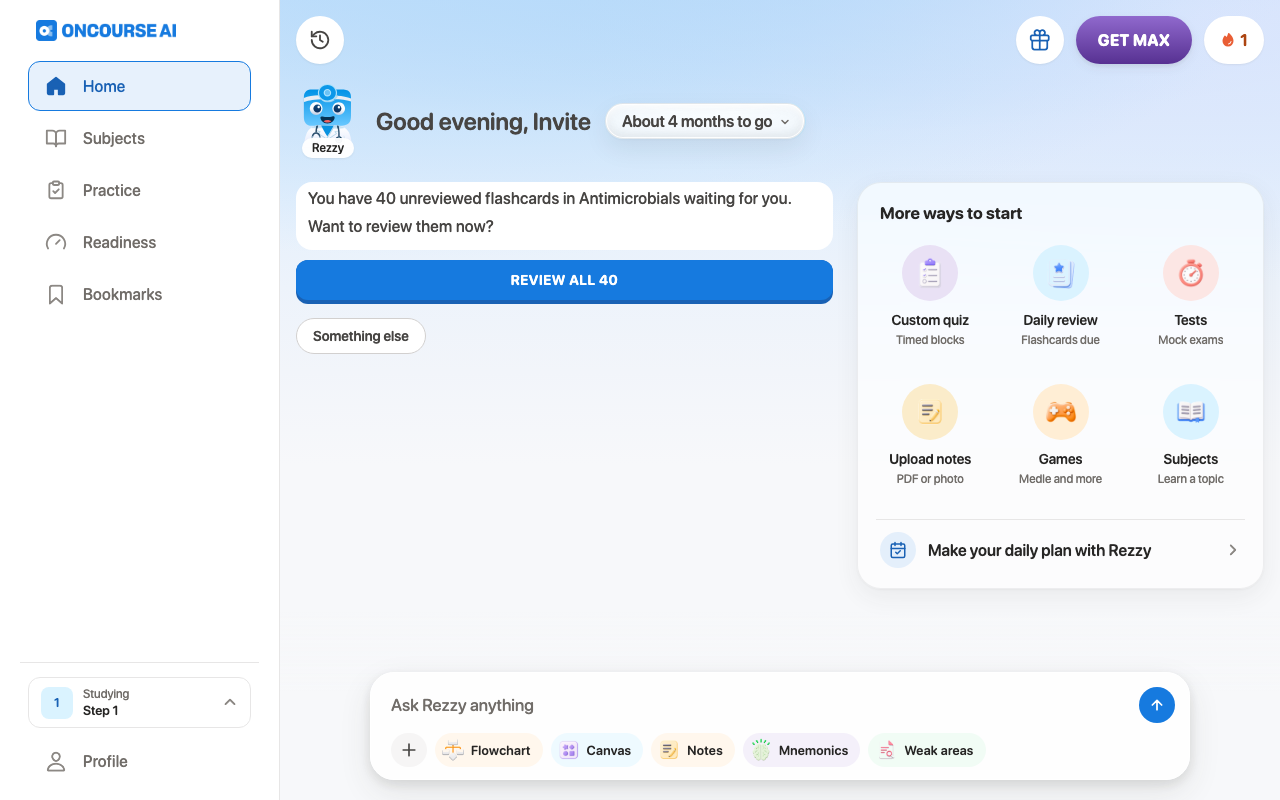
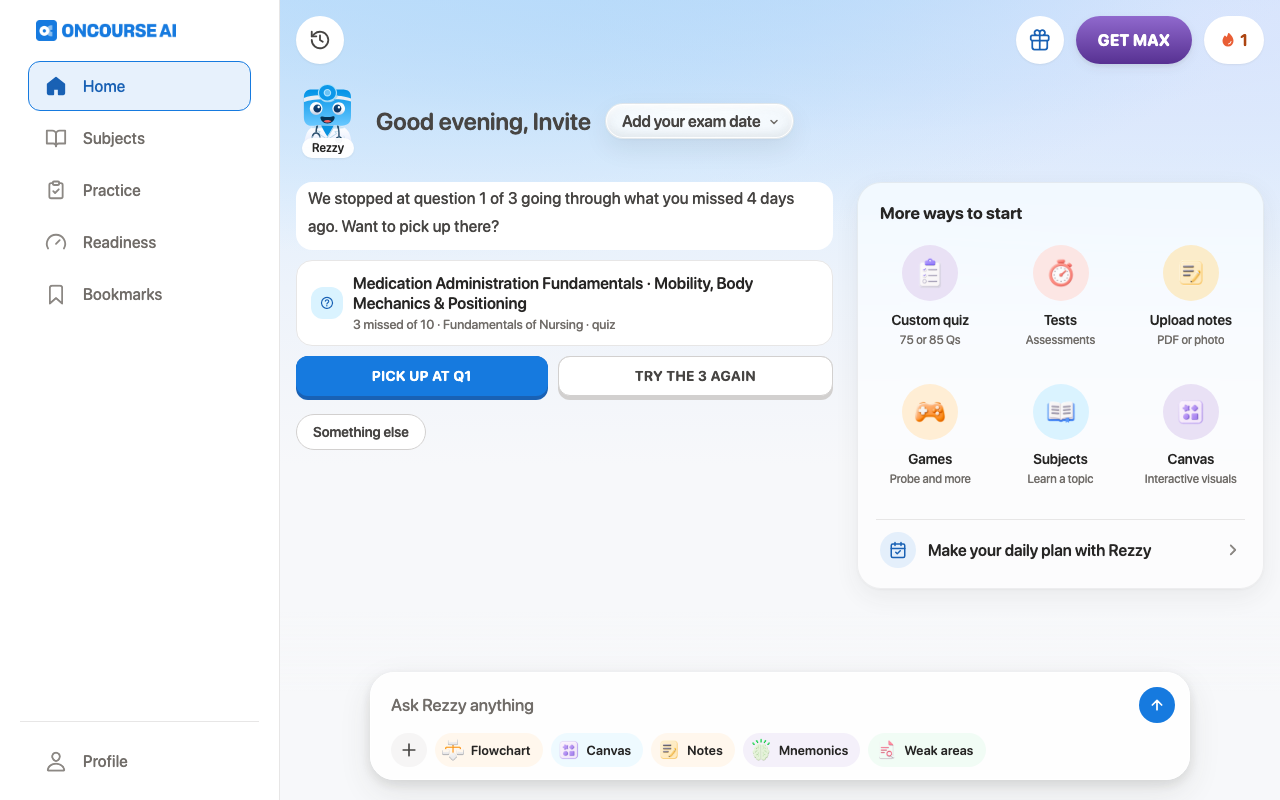
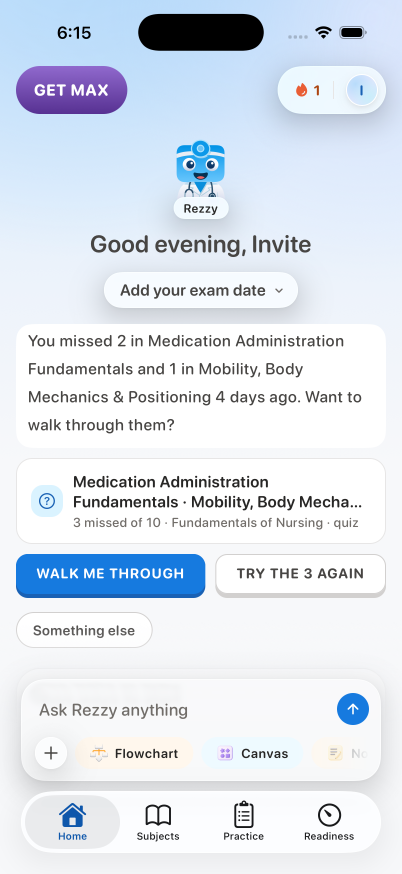
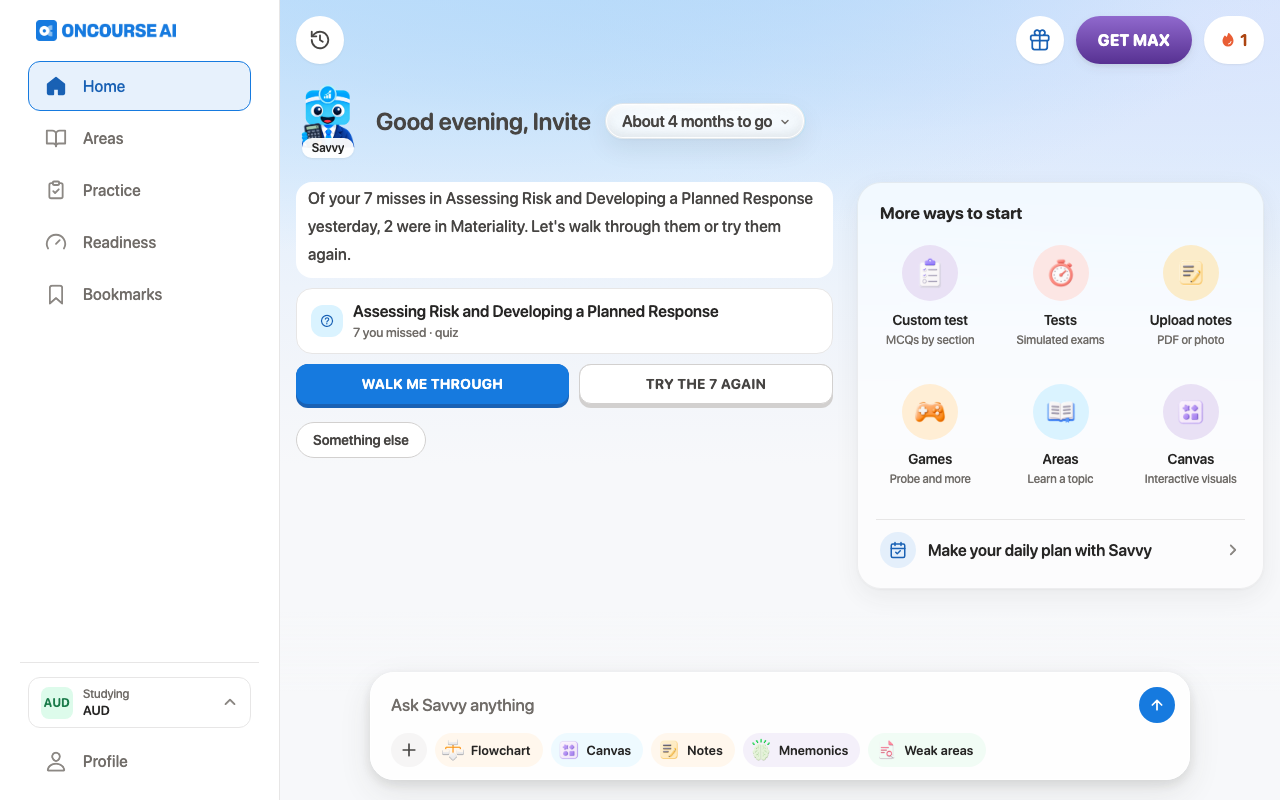
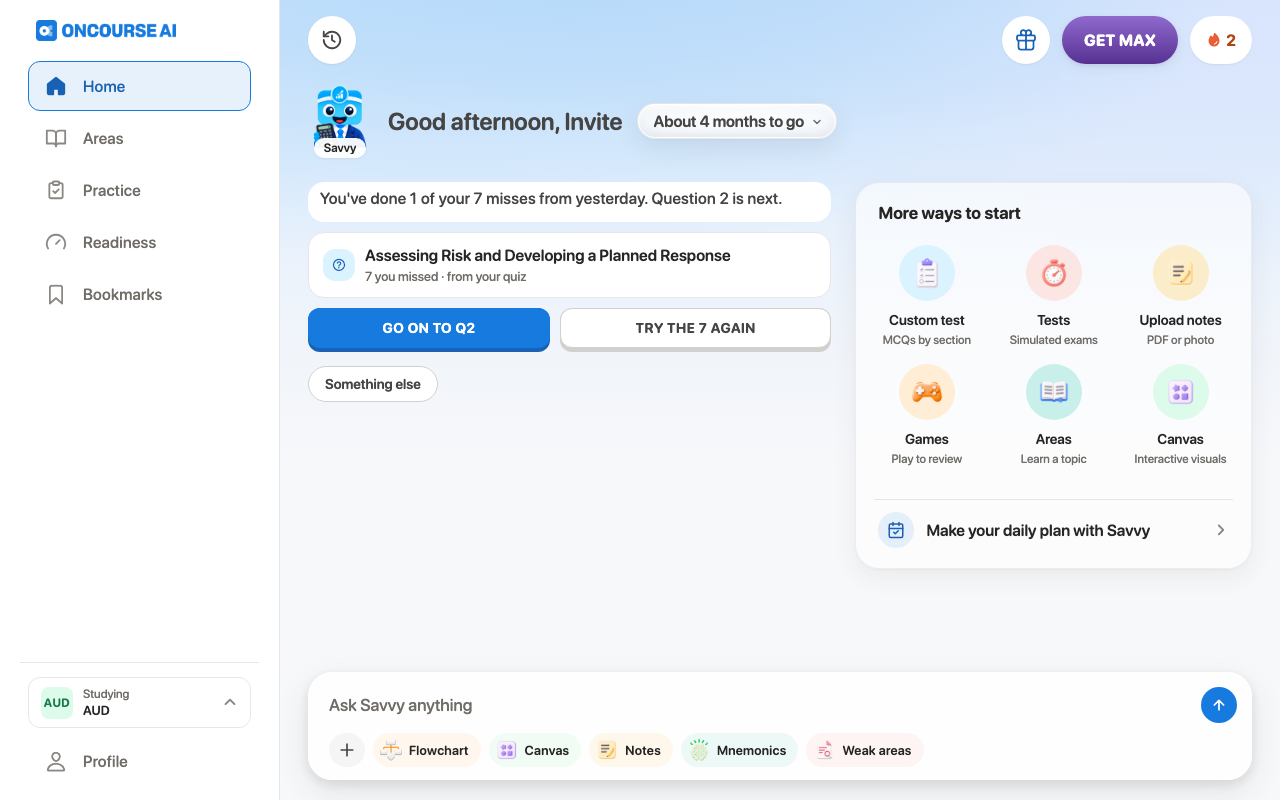
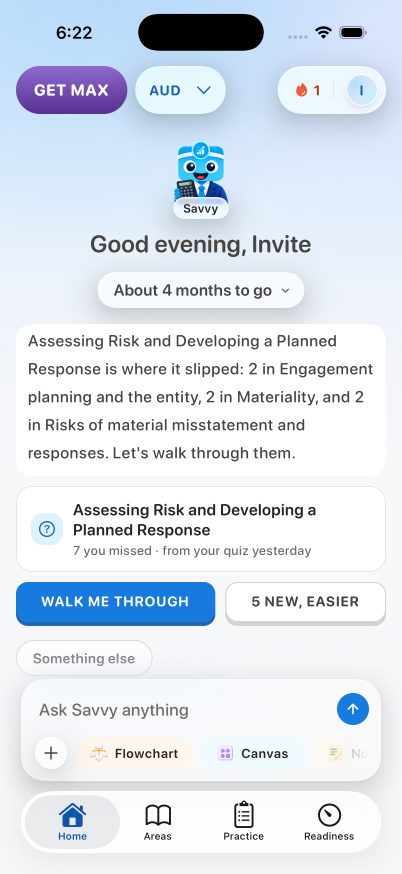
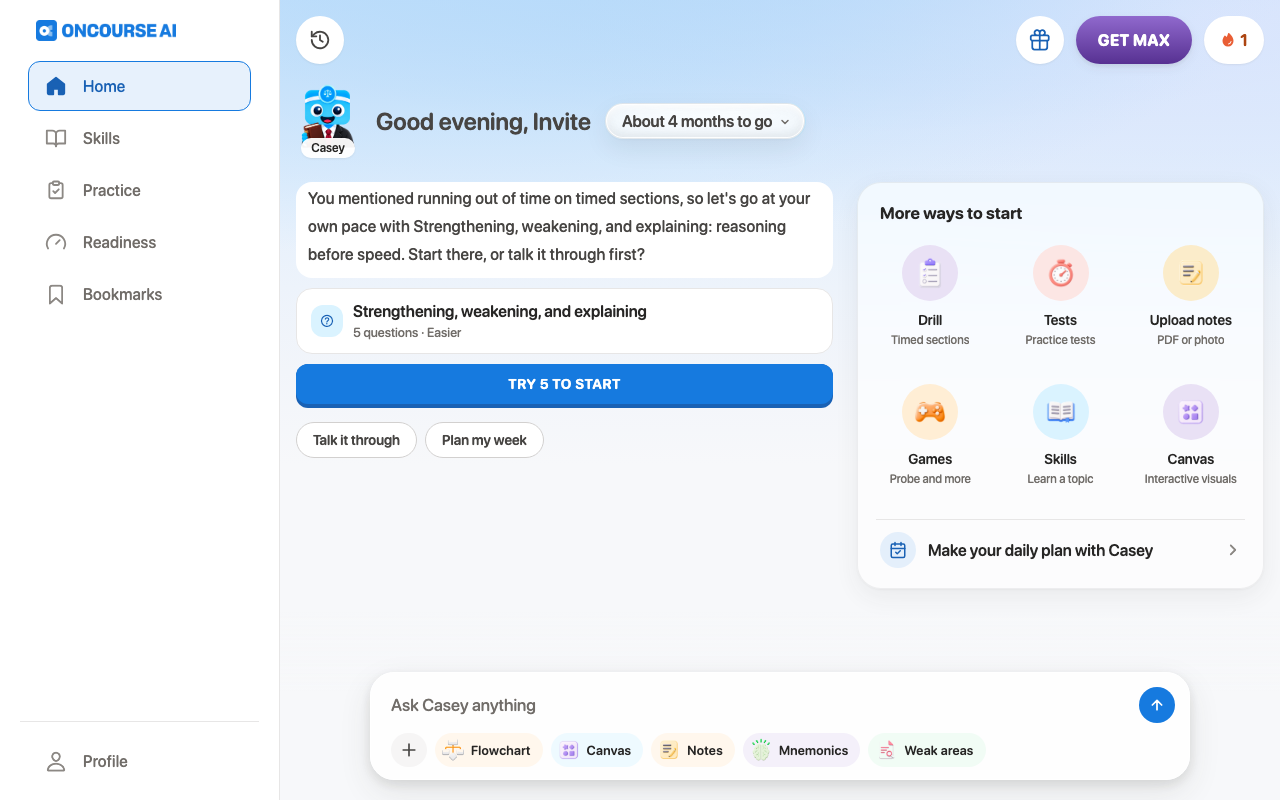
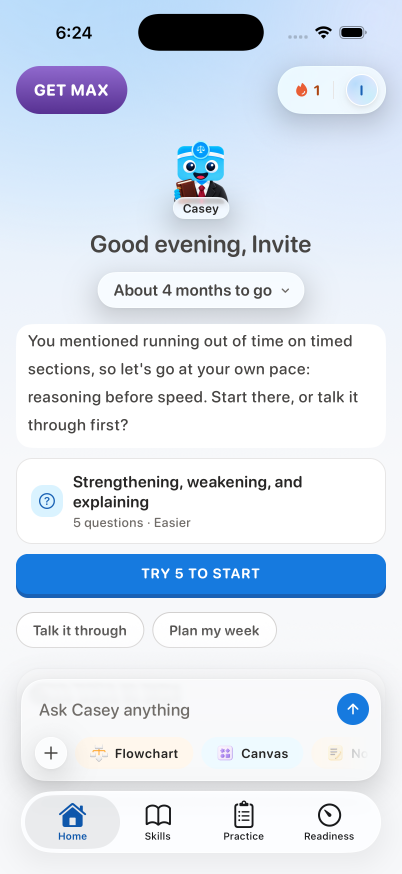
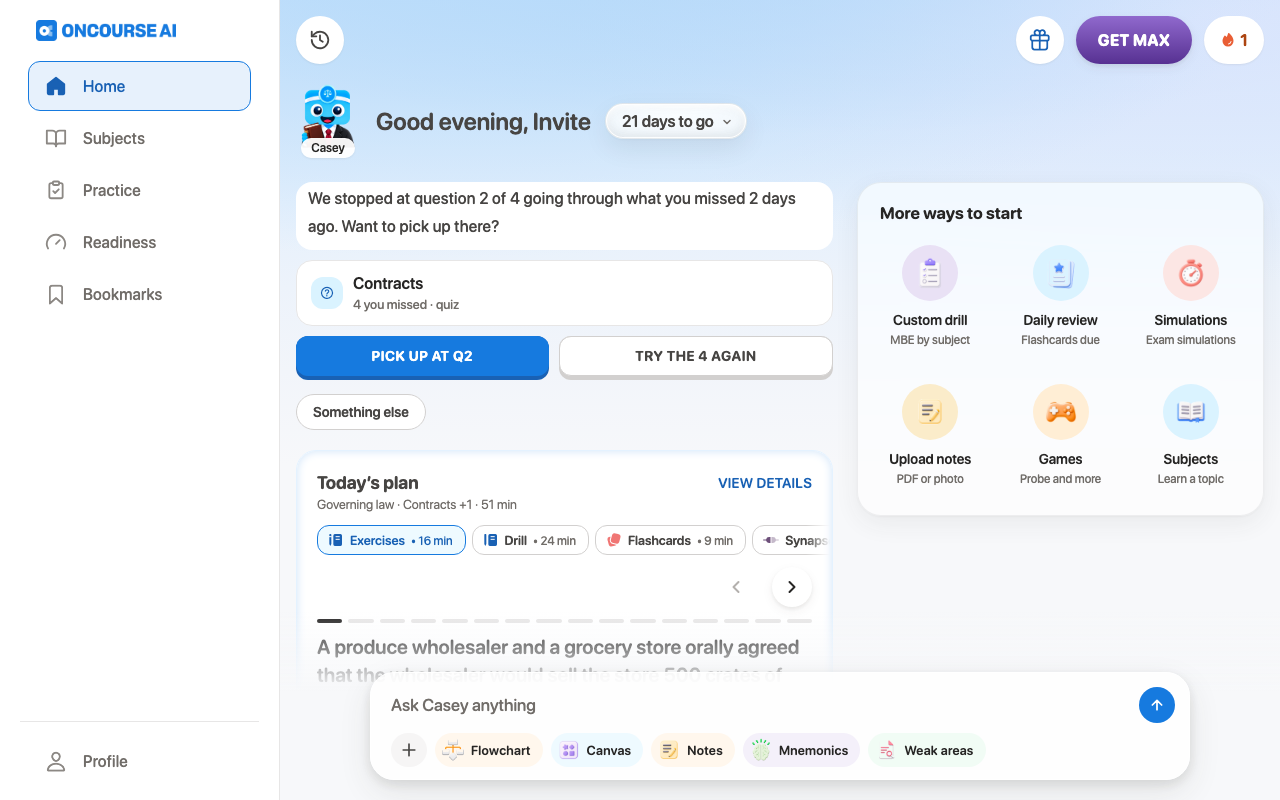
When a learner opens Home, their course's tutor (Rezzy for the medical courses, Savvy for CFA and CPA, Casey for LSAT and the Bar) opens with one short message about what the learner did last, and one or two things it can do about it right now: a quiz on the exact questions they missed, their due cards, the lesson they should read next, or a question they can answer with a tap. Each tap lands where it says: a quiz already built, a screen, or a chat that starts from the card.
Code decides what is possible and true; one model call decides what is worth saying today and says it in the tutor's voice; code checks the result before the learner sees it.
How it works, end to end
Snapshot. SQL reads only the active course (and its selected exams): recent sets and their misses, lessons read, due and forgotten cards, readiness trends, exam date, rhythm, onboarding and the tutor's memory notes.
Offers. Code turns the snapshot into things the app can run today, each with real ids and one count used by its label, its facts and its target.
Compose. One structured call (Gemini 3.5 Flash Lite) picks one or two offers and writes the message, buttons, chips and at most one block.
Validate. Every id is an offer; every number belongs to an offer the card uses; no other course's exam or tutor; the rules the model breaks most. A failure retries once with fixes, then falls back to a card built from the rules.
Cache. Stored per learner, course and exam scope with a fingerprint of the data; an unchanged learner gets the stored card in ~0.1 s.
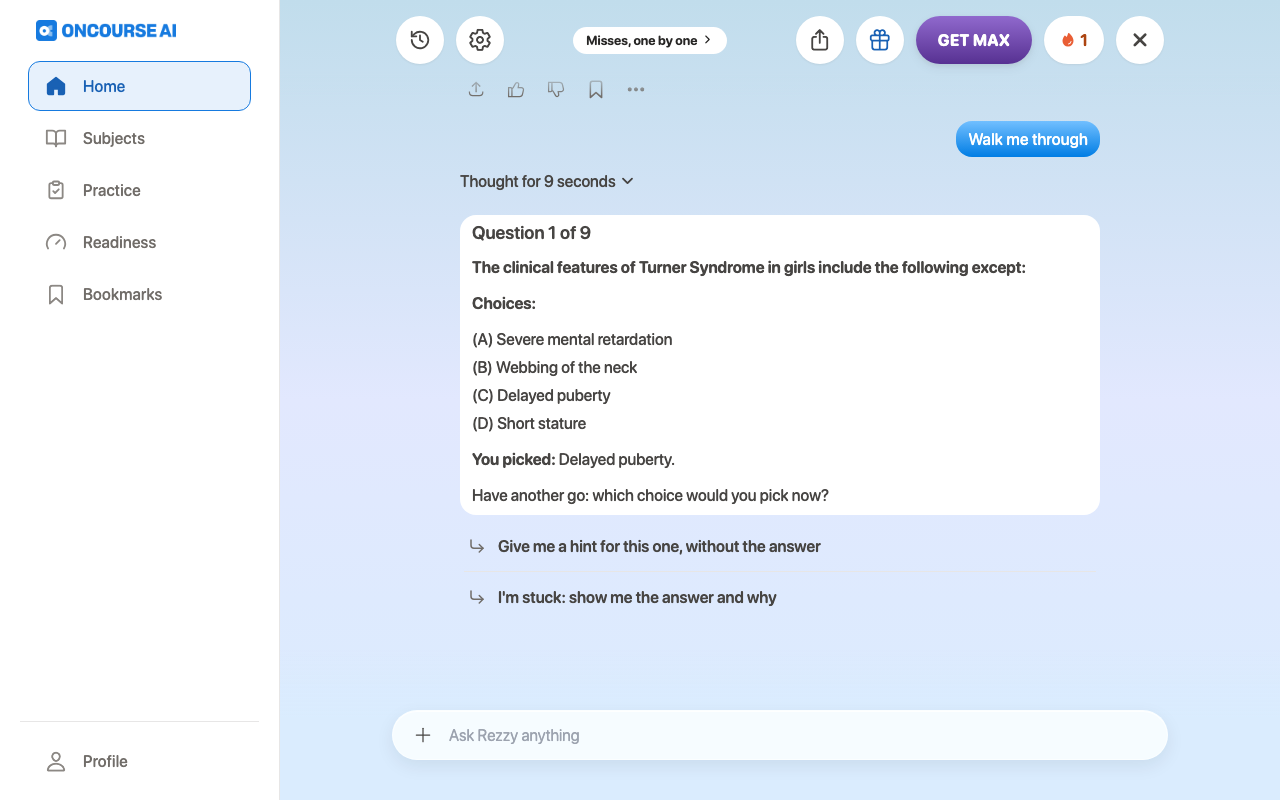
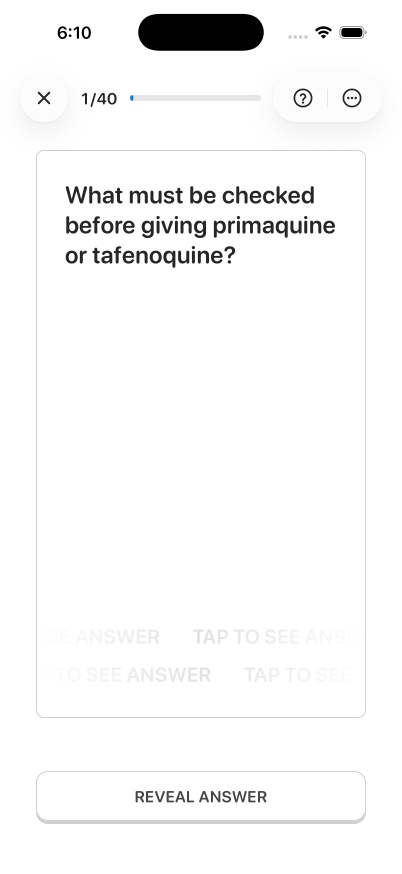
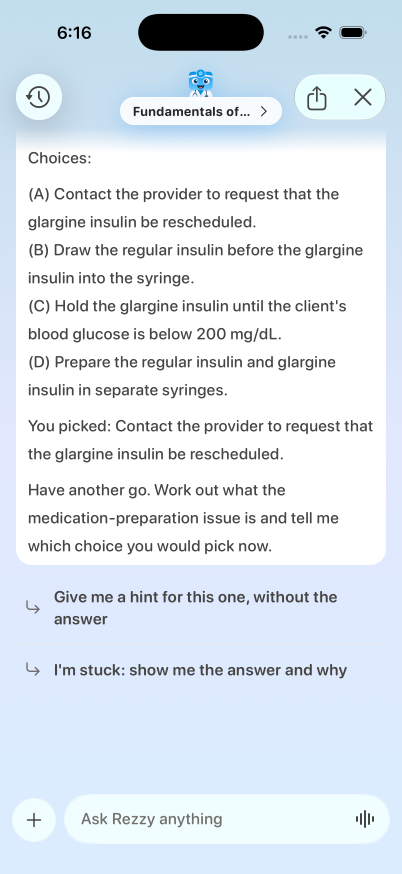
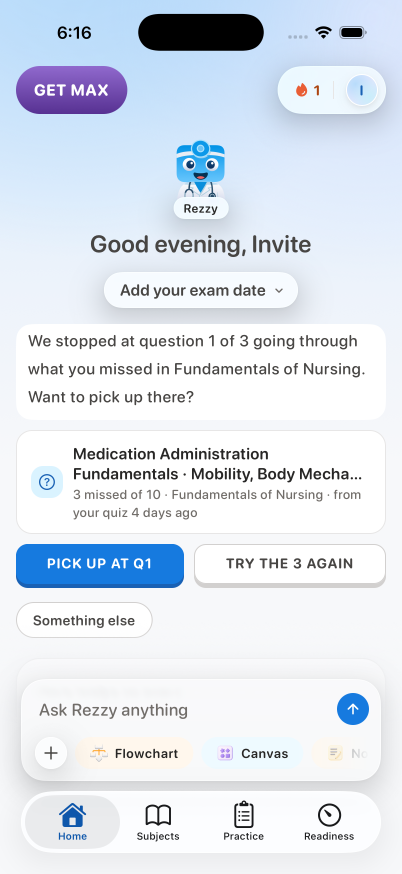
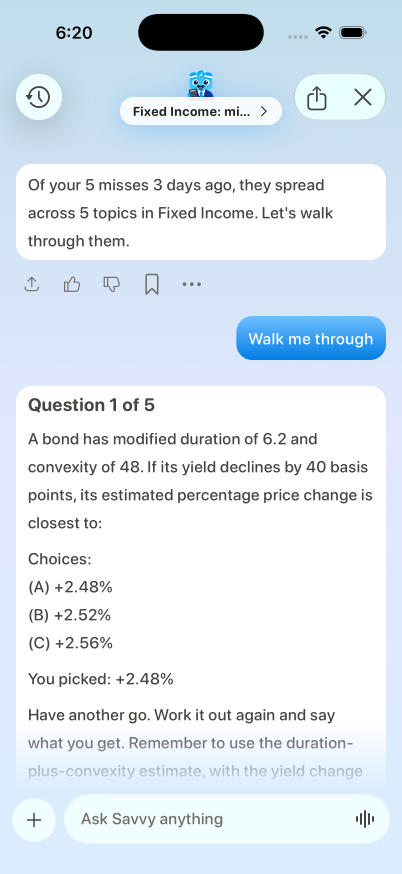
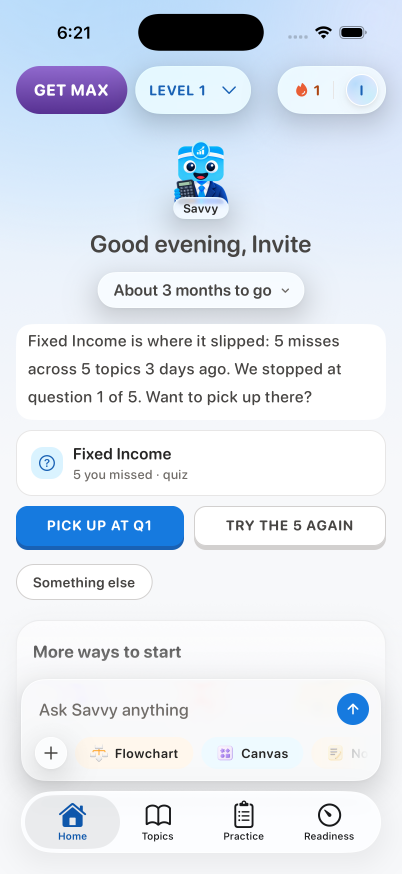
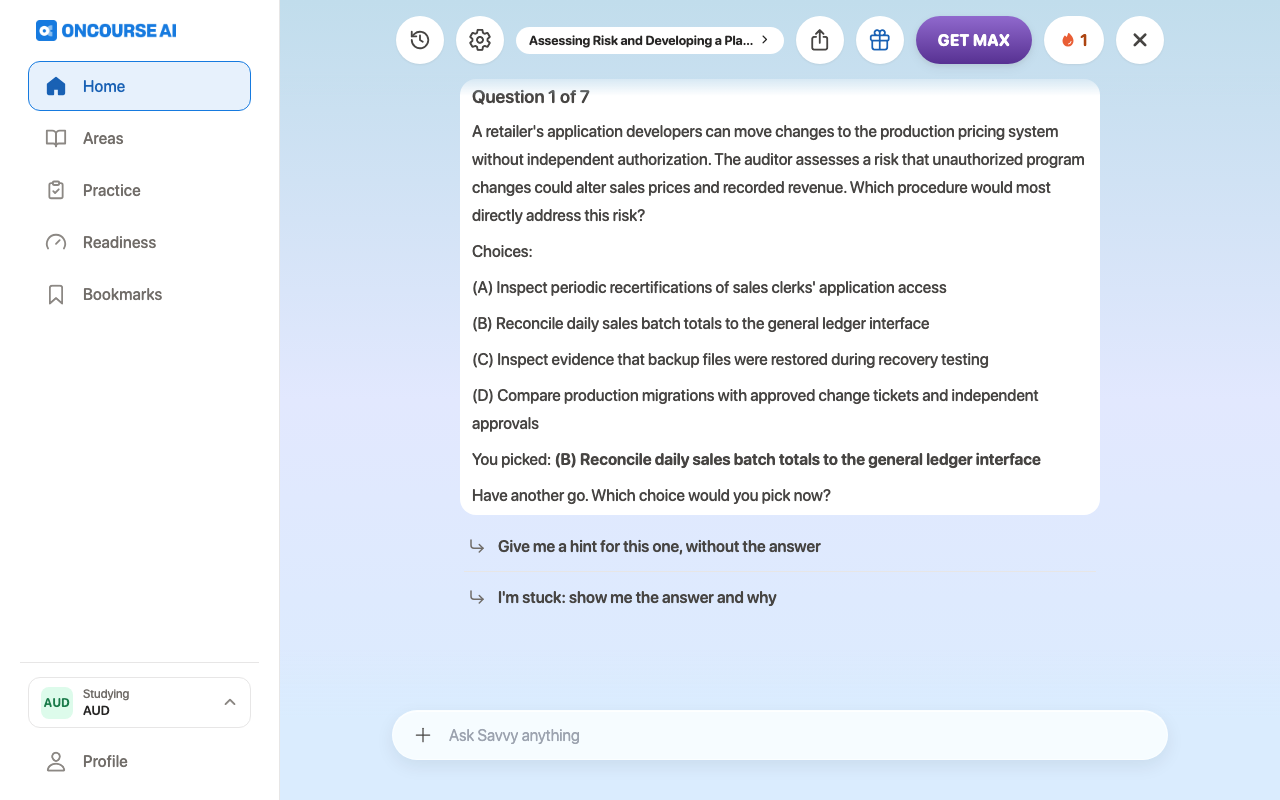
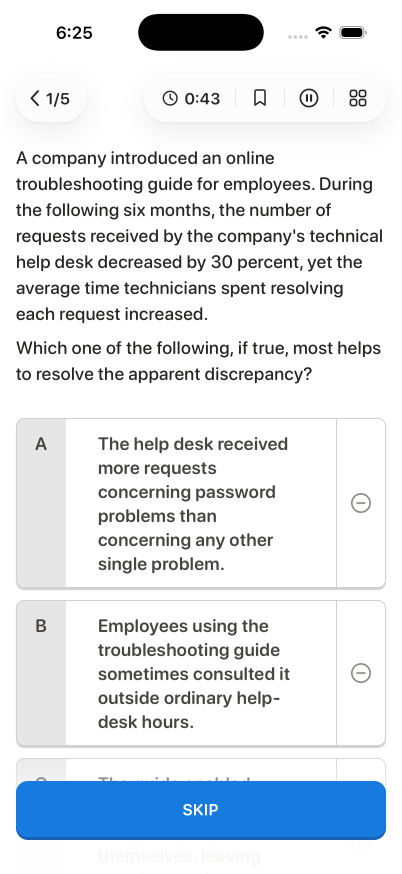
Act. A tap goes to the server, which resolves the offer on the stored card (a quiz template from the exact question ids, a route, or a chat whose first bubble is the stored message and whose first turn follows the offer's plan).
Component catalog
The model picks components by reference; the app draws them from design-system parts. It can't put a number or an id in one.
Component
What it shows
question_set
The set an offer is about: topics, "4 missed of 10", source, when. From the offer's facts, never model text.
flashcard_peek
How many cards, the topic, and the front of the shortest card (a cloze is blanked).
lesson_peek
The lesson's title, subject and minutes.
subject_bars
Readiness bars for the subjects the message names, with their trend.
Buttons
One or two actions, the first primary. Each is an offer id.
Chips
Replies: a check-in's answers, or "Something else" to answer in their own words.
Action registry
Offer kind
Opens
Resolved as
quiz_set
A quiz on the exact questions they missed
a test template made at tap time, one per card and offer
quiz_topic
New questions on a subject or topics (PYQs where the course has them; five easier ones as a small win)
picked at tap time
flashcards_due
Review of their due cards in this course
route
flashcards_ids
Review of exact cards (forgotten 3+ times, never reviewed)
route
lesson
A lesson by id
route
game
A game on a subject where the course has it
route
open_chat
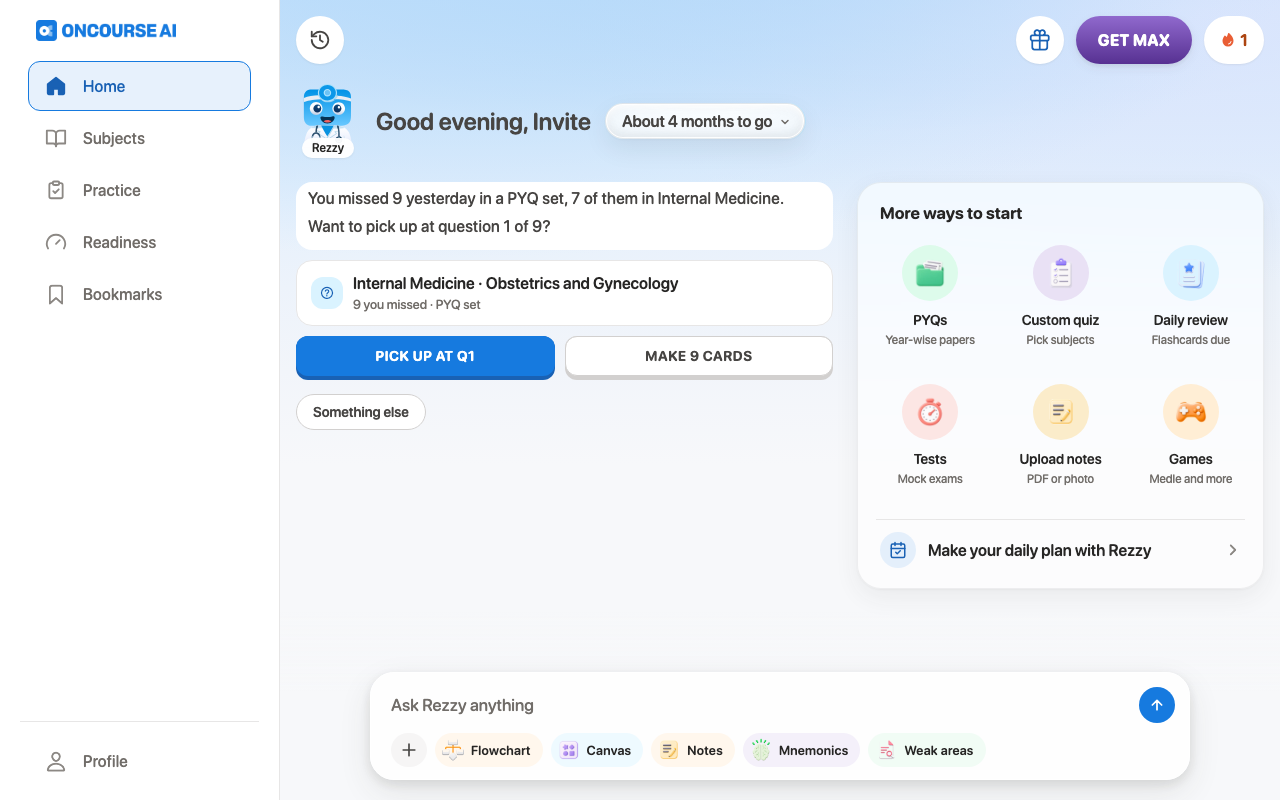
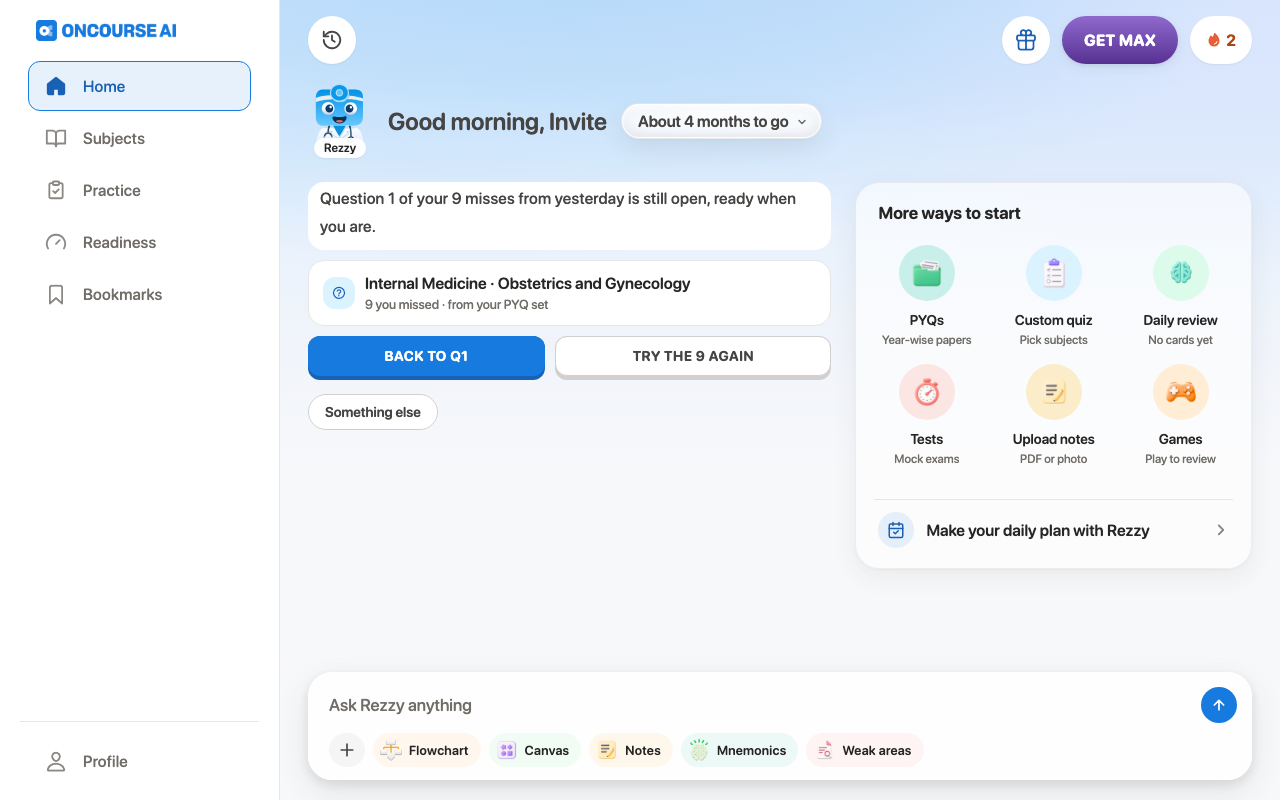
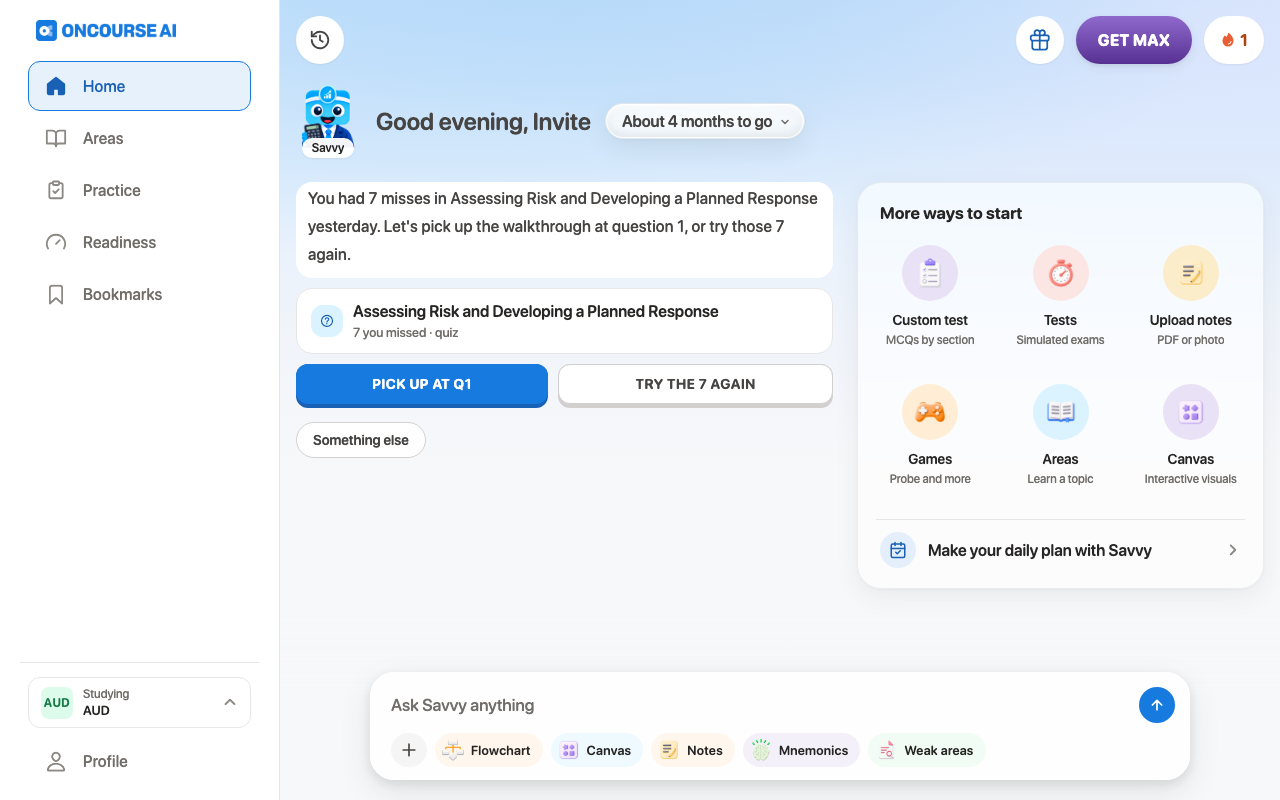
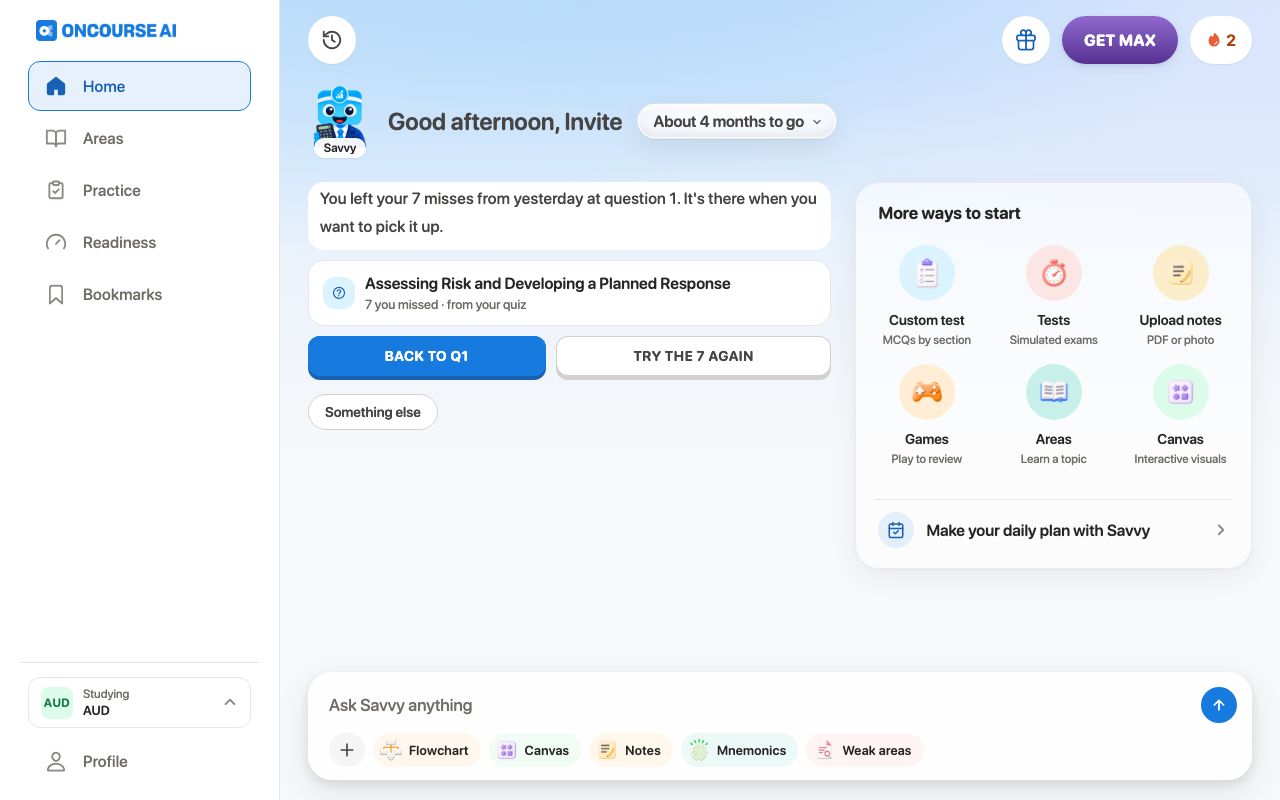
The walkthrough chat they left, at the question they reached ("Pick up at Q3")
route to that chat
chat
The tutor's chat, seeded: explain misses, cards from misses or a lesson, review cards, mini lesson, summary, plan the exam, check-ins
chat with a server-side plan
Latency and cost
Eval v11b at api 4762e561 (the commits after it change prompt copy and add checks): the full set of 162 synthetic learners across the nine courses, in the situations each course meets (misses, a lesson read, due cards, an exam passed, a walkthrough left part way, a new learner, back after a break, big piles, one-topic sets). The rules write the card for the 9 with a walkthrough to pick up, with no model call; the other 153 get one Gemini 3.5 Flash Lite compose each through the api's provider setup, one retry with the validator's errors, then the rules' card. A second model (Gemini 3.6 Flash) judges each valid card.
Valid on the first call: 118 of 153 (77%). After one retry: 143 of 153. Fallback to the rules' card: 10 of 153 (7%).
Latency: first call p50 1.19 s, p95 1.50 s; whole compose with its retry p50 1.26 s, p95 2.71 s, max 5.5 s.
Cost per compose: $0.00137 mean, retries included (about 3,800 tokens in, 160 out, from the live staging log).
Output judge: 139 of 143 valid cards pass all four checks (person, times, claims, fit); voice 4.42 of 5.
Live, on staging: the nine QA learners' cold opens one at a time at api 9804566b: 9 of 9 composed, p50 2.59 s, worst 4.7 s end to end, 3 on a second attempt, $0.0011-0.0027 each. A stored card returns in about 0.1-0.4 s.
Model
Runs
Valid first try
Valid after retry
Fallbacks
First call p50 / p95 / max
Whole compose p50 / p95 / max
Mean cost
gemini-3.5-flash-lite
153
118
143
10
1187 / 1504 / 4905 ms
1258 / 2709 / 5450 ms
$0.00137
Model
Judged
Pass all four (person, times, claims, fit)
Mean voice (1-5)
gemini-3.5-flash-lite
143
139
4.42
At one fresh card per active learner per day, 10,000 learners cost about $14 a day. The walkthrough chat uses the existing chat model; its first turn takes about 8 s on staging.
Which model should write the card? A benchmark
Recommendation: GPT-6 Luna at low reasoning effort, through the AI Gateway. In a blinded read it wrote the best cards (step 4.73 of 5, no factual errors in 15), with no fallbacks and 13 of 15 valid on the first call. It costs about a quarter of today's model at list price ($0.00054 against $0.00233 per Home render, about $5 against $23 a day for 10,000 learners). The price is about half a second: a full card's p50 is 2.6 s against 2.1 s, and 1 card in 15 took 7.0 s, past the 6 s inline budget, so the rules card stays as the backstop. Run the full 162-learner eval on it before switching. GPT-6 Luna at none is the faster runner-up (worst 5.2 s, step 4.13).
Medium and high effort don't suit an inline card: 7 and 15 of 15 cards went past 6 s, and they wrote no better cards. DeepSeek V4.1 Flash with thinking off is the fastest to a first card (p50 1.3 s), but it fell back 3 times in 15. With thinking on it is slow (full card p50 8.5-8.7 s, worst 43 s) and costs 2-3 times today's model.
Model, effort
First card p50 / p95
Full card p50 / p95 / max
Over 6 s
Cost per render
Valid first / after retry / fallback
Judge pass
Voice
Main = top offer
List price, uncached
Blind step / voice (1-5)
Factual errors (blind)
Gemini 3.5 Flash Lite, thinking low (today)
1.7 / 2.1 s
2.1 / 3.4 / 3.5 s
0 of 15
$0.00136
8 / 14 / 1 of 15
14 of 14
4.86
14 of 14
$0.00233
3.13 / 3.20
0 of 15
GPT-6 Luna, none
2.3 / 2.5 s
2.4 / 5.2 / 5.2 s
0 of 15
$0.00020
10 / 15 / 0 of 15
15 of 15
4.80
15 of 15
$0.00063
4.13 / 3.27
0 of 15
GPT-6 Luna, low
2.4 / 2.9 s
2.6 / 5.4 / 7.0 s
1 of 15
$0.00019
13 / 15 / 0 of 15
15 of 15
4.80
15 of 15
$0.00054
4.73 / 3.60
0 of 15
GPT-6 Luna, medium
5.9 / 8.1 s
5.9 / 13.2 / 18.7 s
7 of 15
$0.00049
13 / 15 / 0 of 15
14 of 15
4.93
15 of 15
$0.00084
4.13 / 3.27
4 of 15
GPT-6 Luna, high
10.4 / 16.2 s
10.4 / 16.2 / 21.6 s
15 of 15
$0.00058
15 / 15 / 0 of 15
15 of 15
4.87
15 of 15
$0.00095
4.47 / 3.20
2 of 15
DeepSeek V4.1 Flash, none
1.3 / 2.7 s
2.2 / 2.9 / 3.4 s
0 of 15
$0.00124
10 / 12 / 3 of 15
12 of 12
5.00
12 of 12
$0.00181
3.93 / 3.67
1 of 15
DeepSeek V4.1 Flash, low
4.7 / 11.8 s
8.5 / 18.3 / 21.5 s
8 of 15
$0.00351
9 / 14 / 1 of 15
14 of 14
4.50
14 of 14
$0.00410
4.40 / 3.07
1 of 15
DeepSeek V4.1 Flash, high
8.3 / 12.0 s
8.7 / 18.6 / 42.8 s
9 of 15
$0.00439
10 / 13 / 2 of 15
12 of 13
4.69
13 of 13
$0.00499
4.13 / 3.13
4 of 15
Inputs: the staging QA learners for Indian and US Medical PG, the Bar, CFA and CPA. Each learner's snapshot and offers were built once and given to every setup unchanged: the api's own prompt, schema and validator, one retry, then the rules card. That is 3 runs per learner and setup, 120 cards, at api 9804566b.
Routes: Gemini 3.5 Flash Lite is today's compose, direct through Google at thinking level low. GPT-6 Luna (the newest Luna: the gateway lists no 6.1) and DeepSeek V4.1 Flash go through the AI Gateway with the AI SDK's reasoning setting. Both use keys the api already has (AI_GATEWAY_API_KEY, GOOGLE_GENERATIVE_AI_API_KEY).
First card is the first model call. Full card is the time until a card that passes the validator, retry included, or the rules card. Cost per render is what the gateway billed, lowered by cache hits on the repeated prompts. List price, uncached is the ceiling.
Judge pass and Voice are the eval's automated judge (Gemini 3.6 Flash), which passed nearly everything. Blind step and voice are a fresh Claude Opus 5.5 reviewer's scores of all 120 cards with the setups hidden behind letters: is the main button the right next step, told truthfully, and does it sound like the course's tutor? That read is what separates the setups.
Caveats: 15 cards per setup is a small sample, and 6 calls were in flight at a time. GPT-6 Luna at low spent almost no reasoning tokens on this structured task. Shipping it needs a gateway registry entry with its price.
Gallery: tutors, courses and states
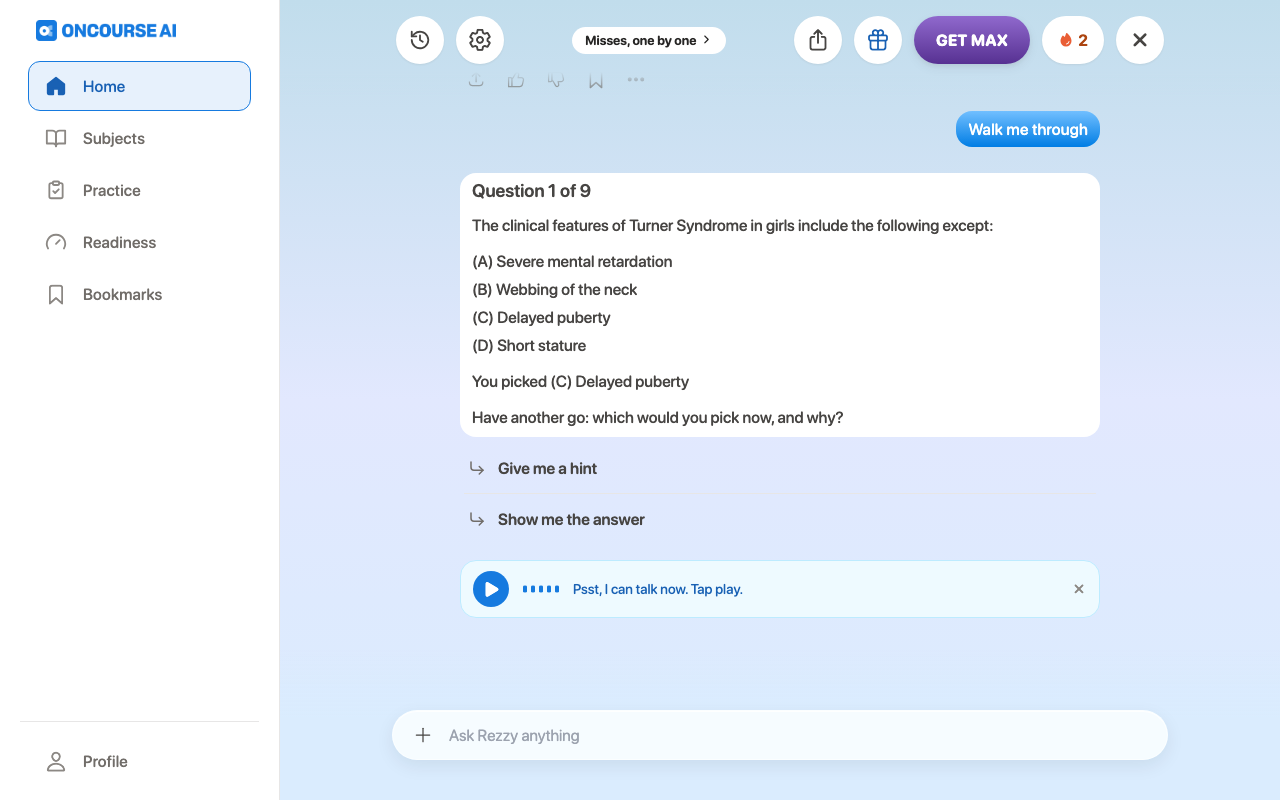
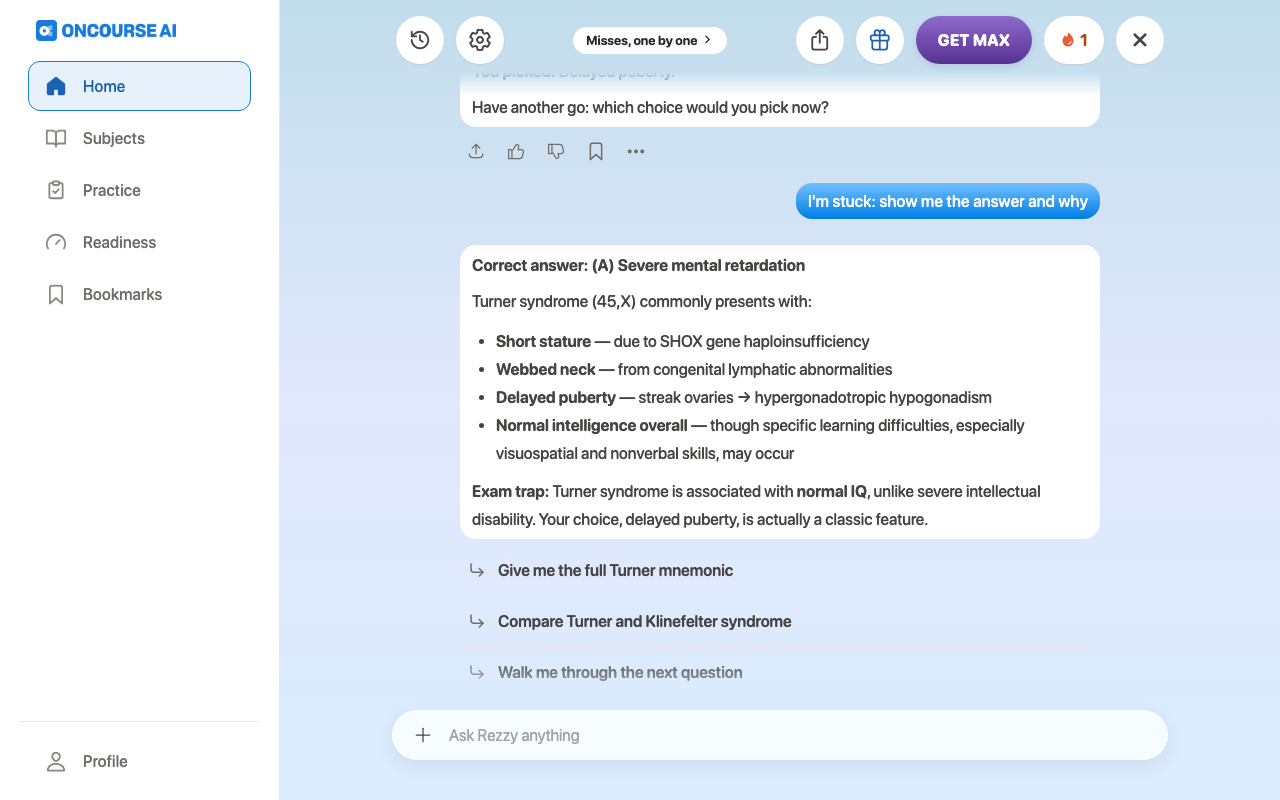
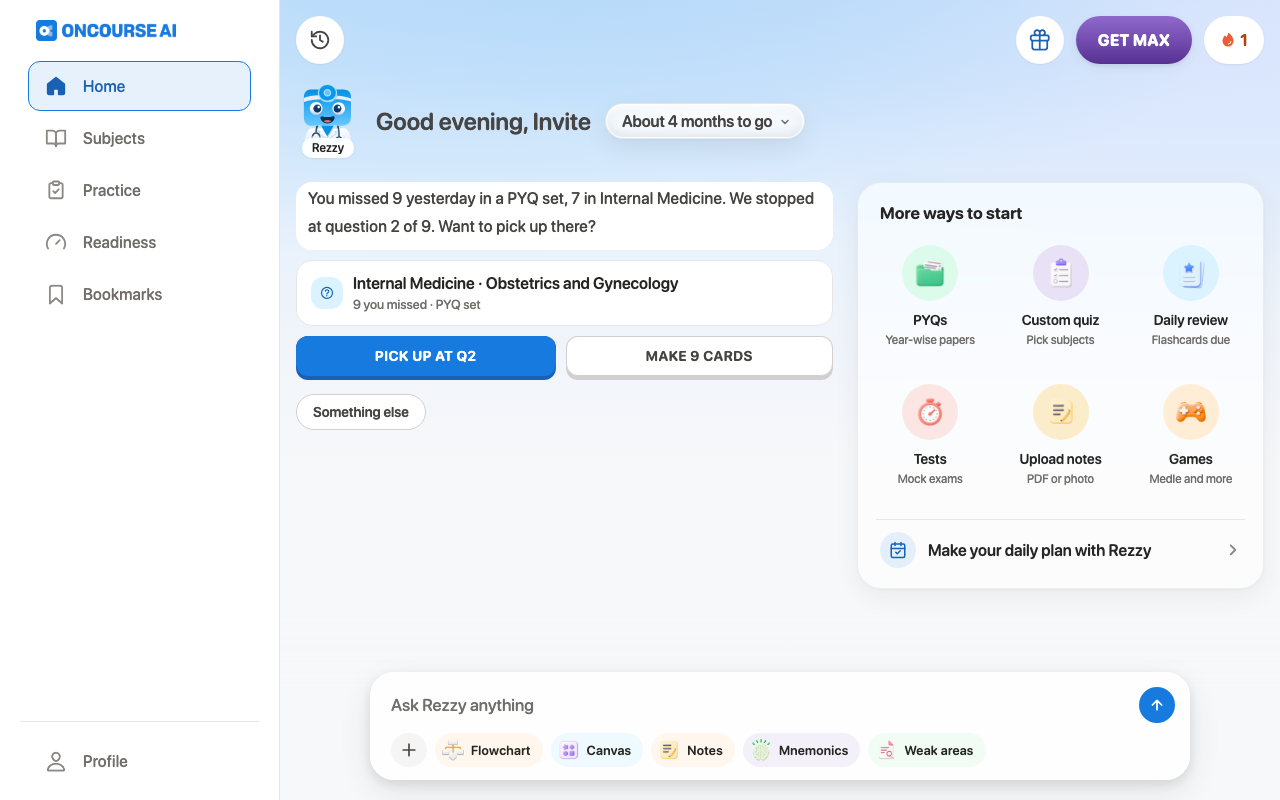
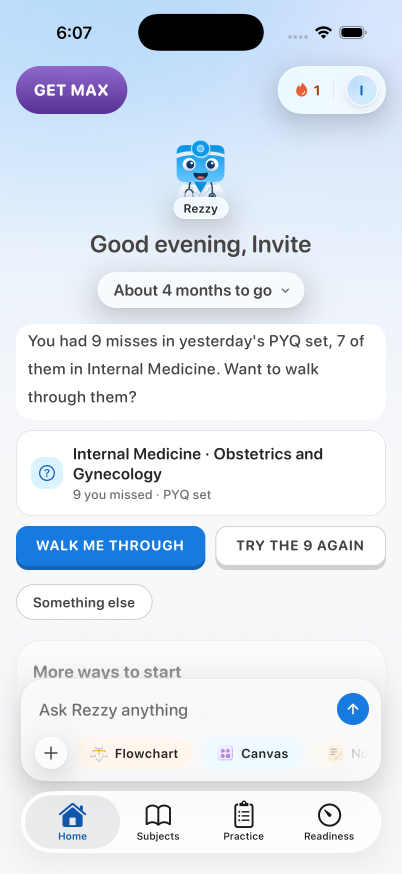
Indian Medical PG (NEET-PG) Rezzy
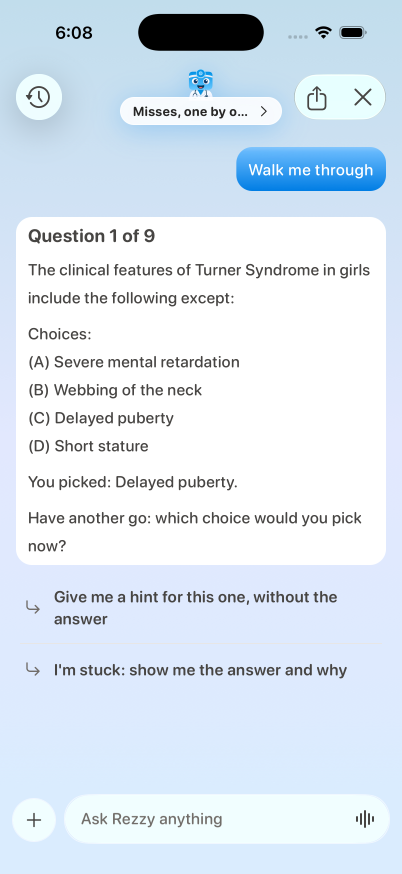
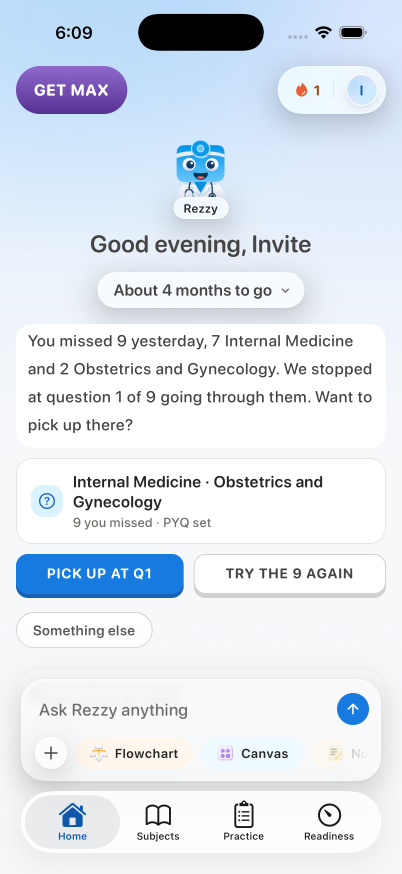
Learner state: a PYQ set yesterday, 9 misses across two subjects
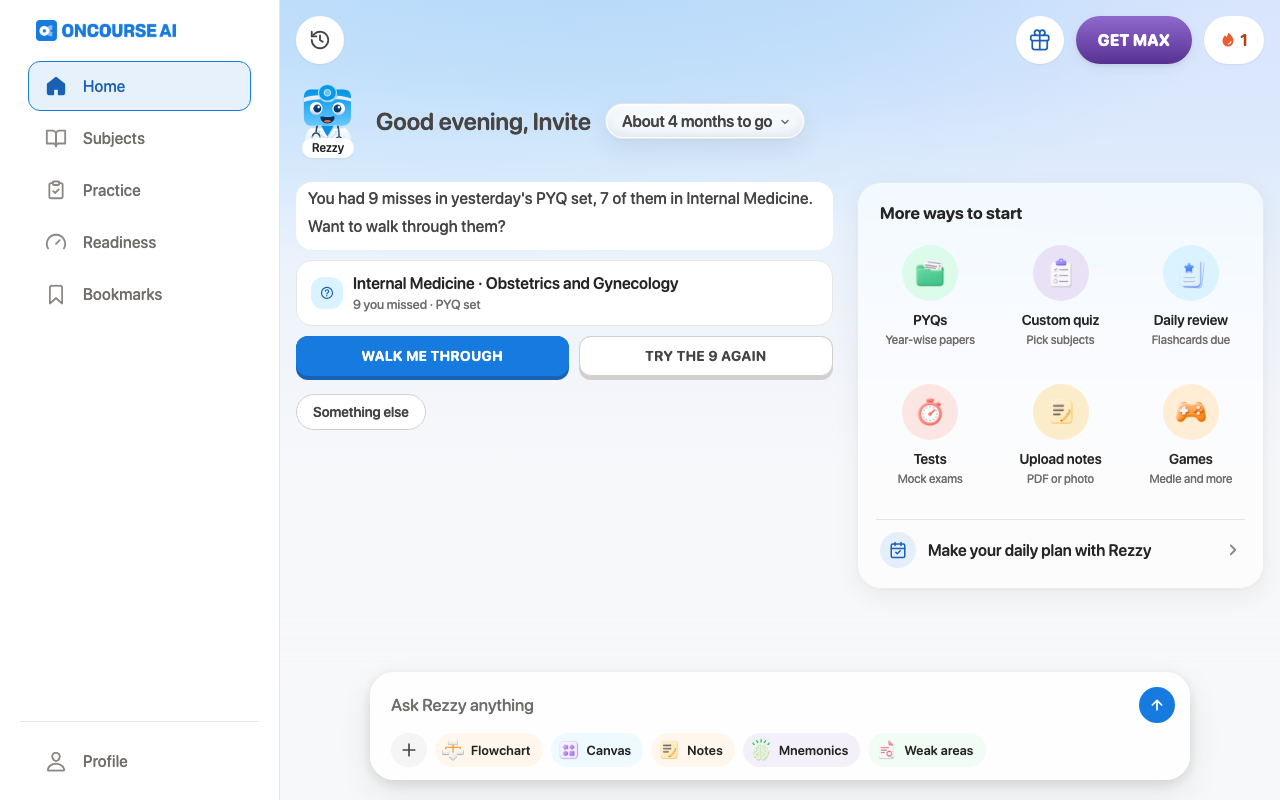
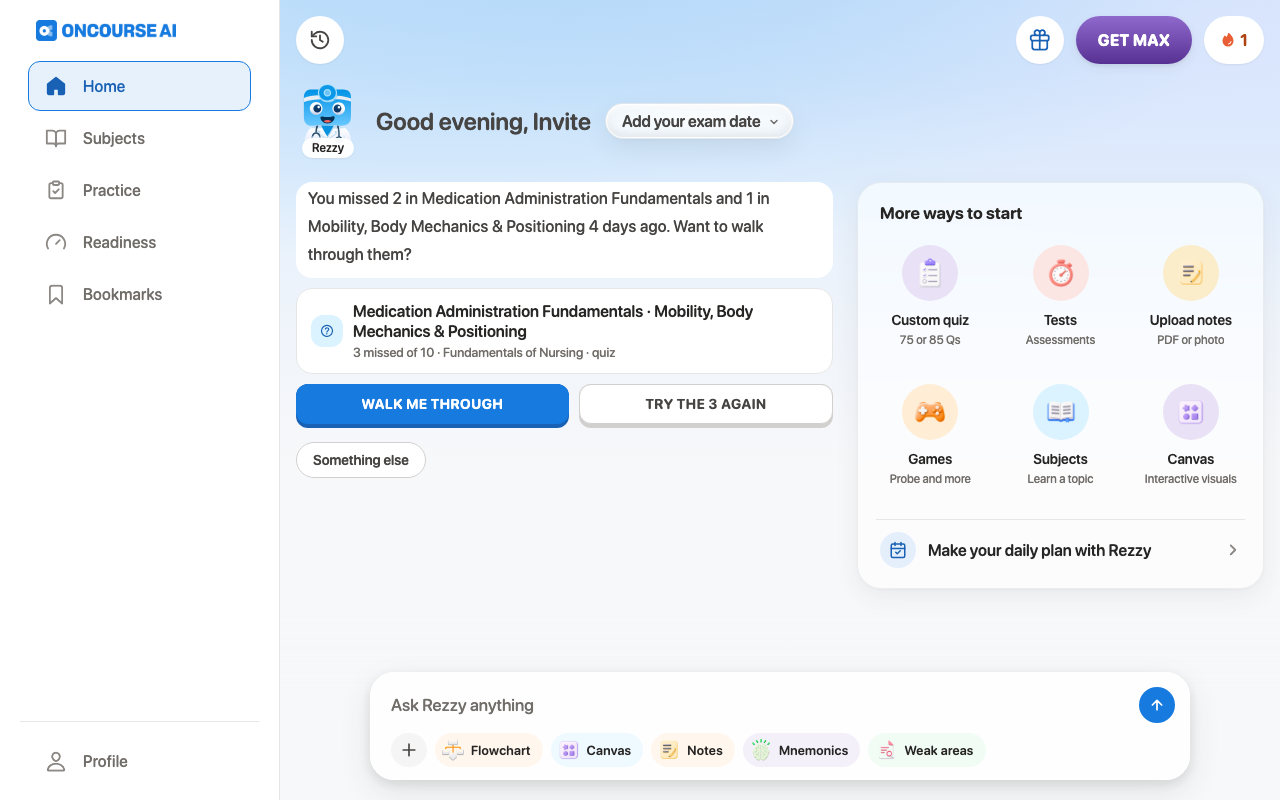
You missed 9 in yesterday's PYQ set, 7 of them in Internal Medicine. Let's walk through those misses together.
Walk me throughTry the 9 again
Something else
block: question_set · source: composed
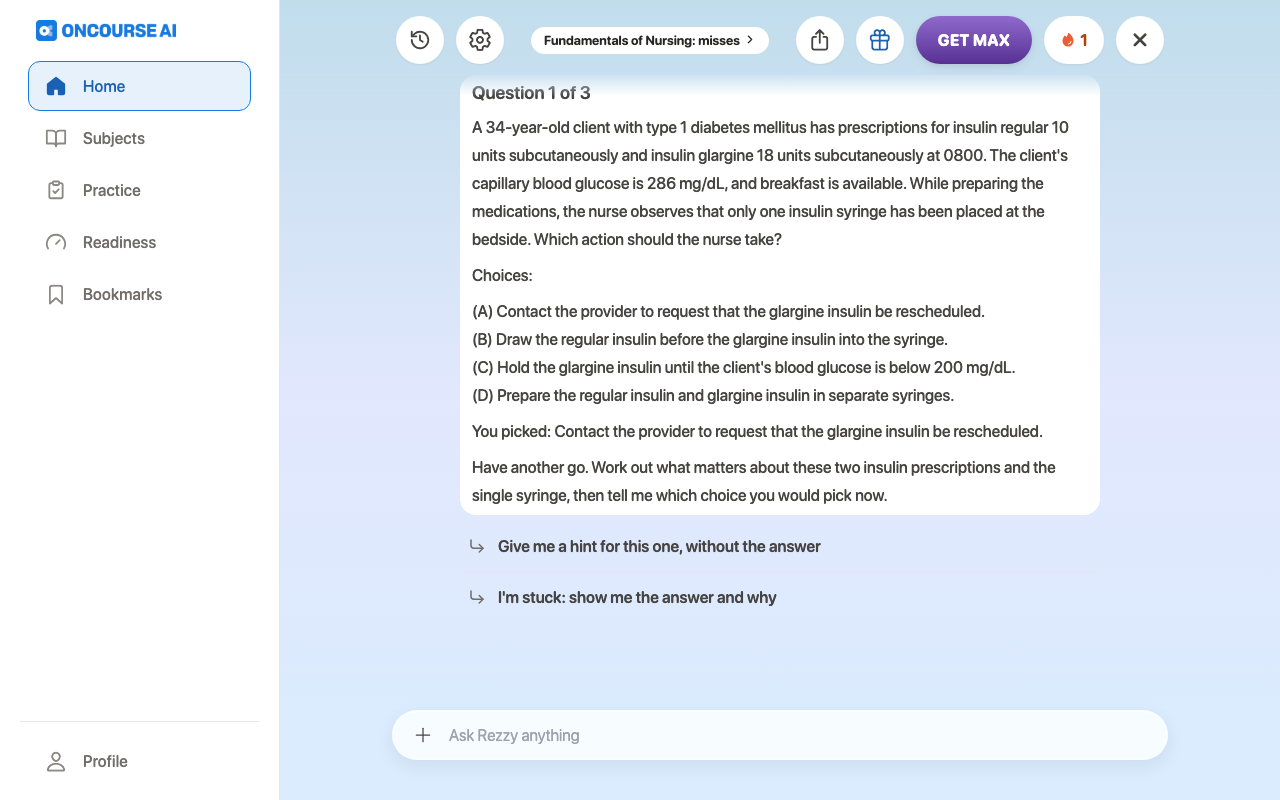
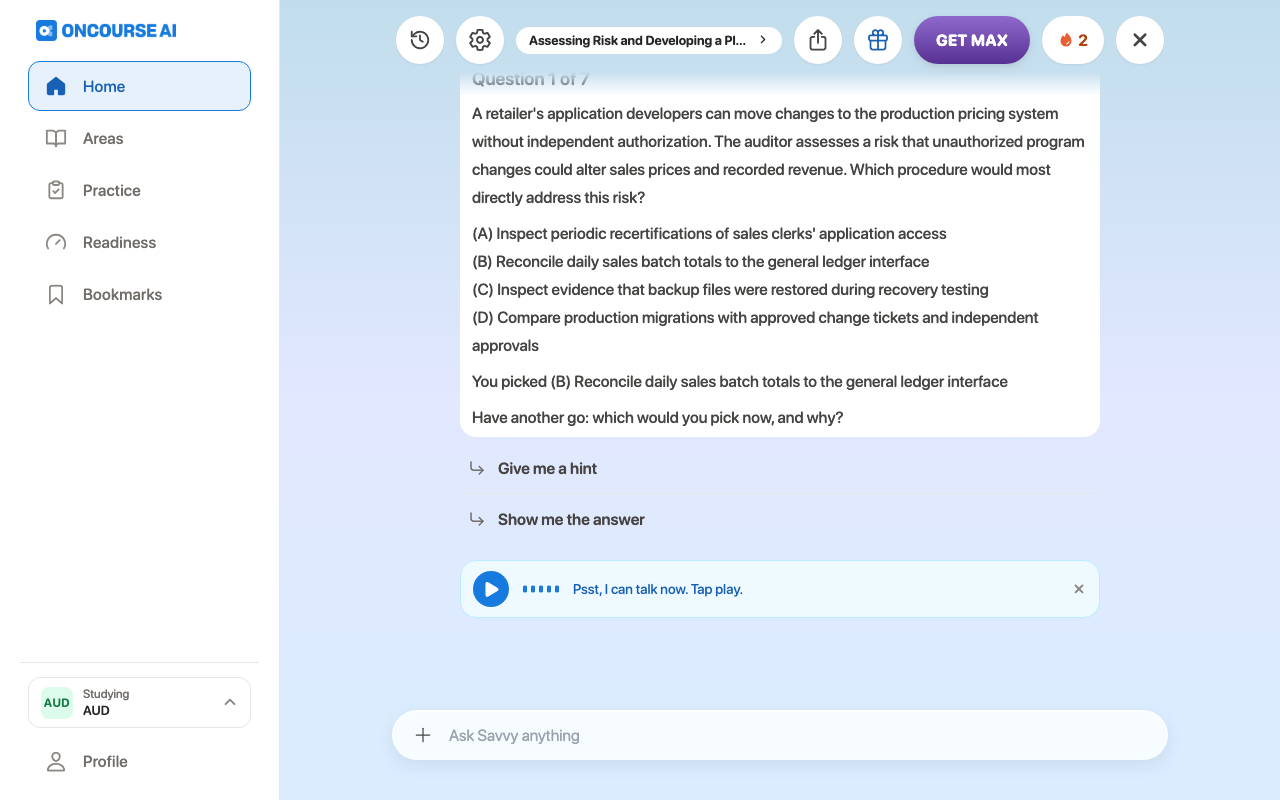
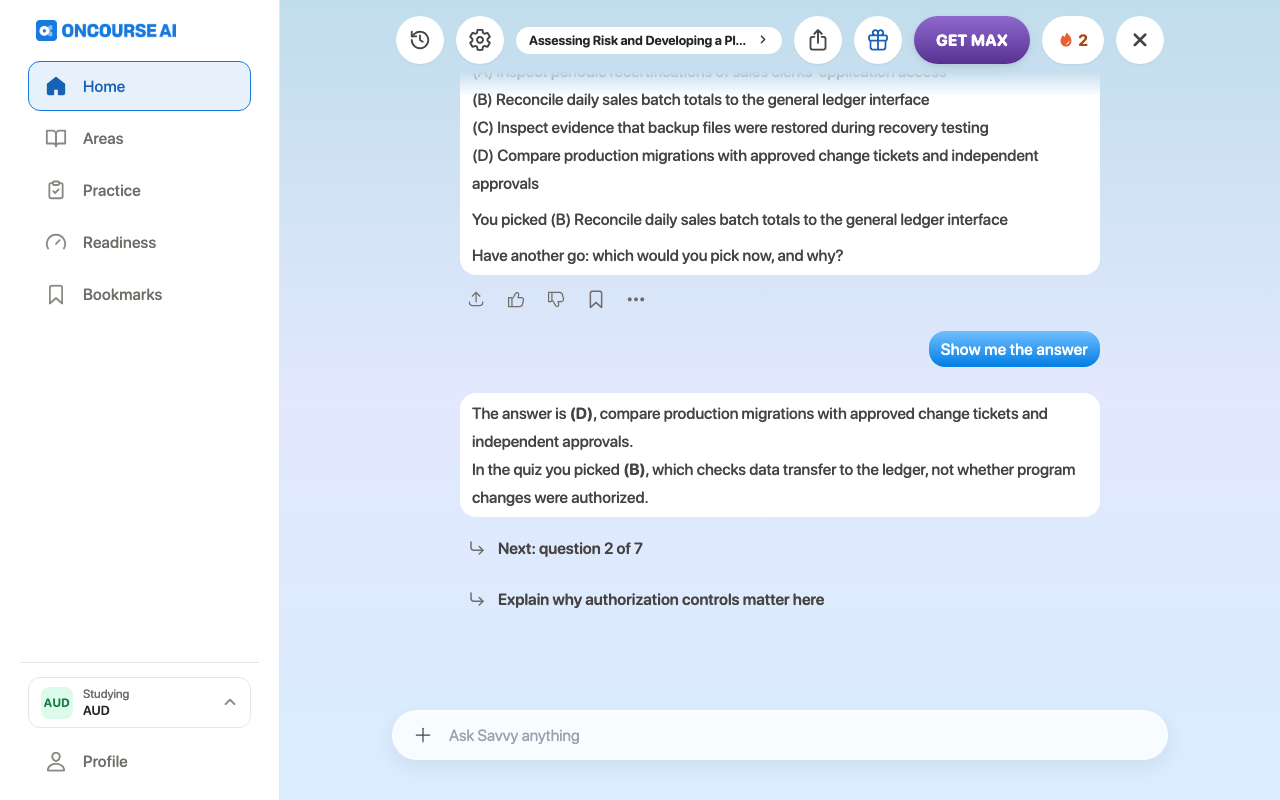
Web: HomeWeb: after the first tapWeb: Home again after the tapWeb: Home offering to pick the walkthrough upWeb: the walkthrough reopenedWeb: walkthrough after one answerWeb: Home after that answeriPhone: HomeiPhone: after the first tapiPhone: Home again after the tap
US Medical PG (USMLE) Rezzy
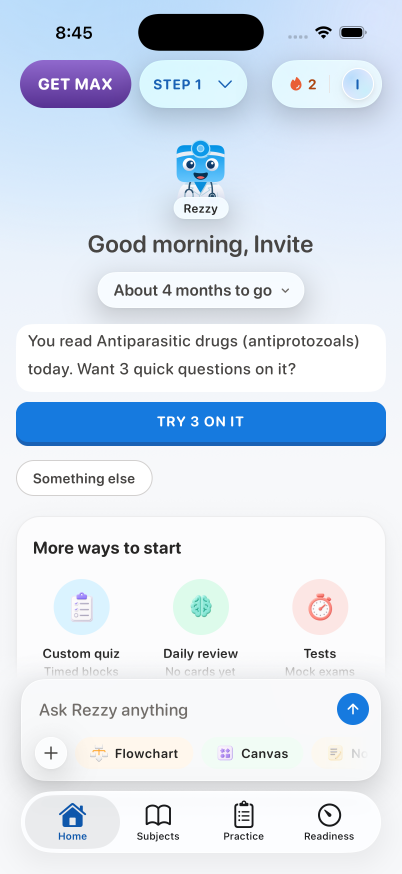
Learner state: read a lesson today, no questions on it since
You read Antiparasitic drugs (antiprotozoals) today. I can turn it into 10 flashcards so it sticks.
Make 10 cardsTry 3 on it
Something else
block: none · source: composed
Web: HomeWeb: after the first tapWeb: Home again after the tapiPhone: HomeiPhone: after the first tapiPhone: Home again after the tap
UK Medical PG (UKMLA) Rezzy
Learner state: exam month set months ago, back after a break
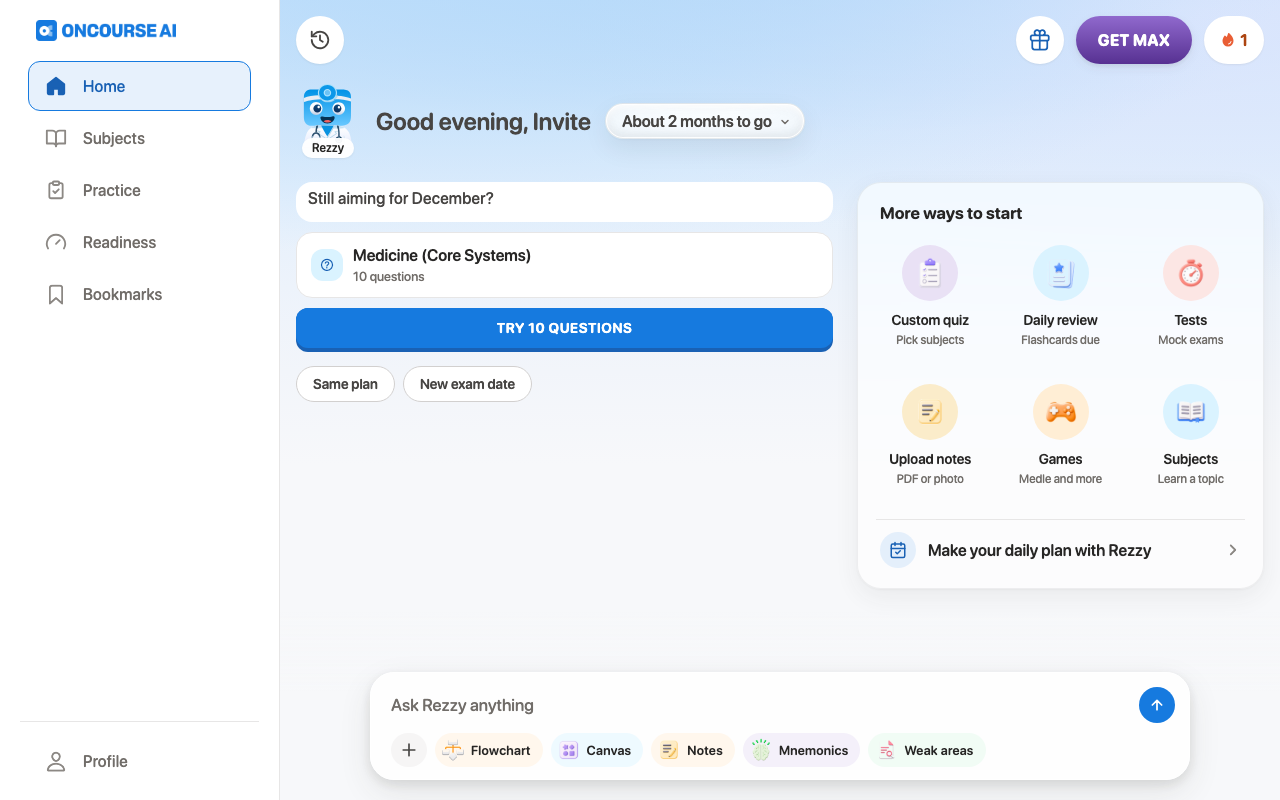
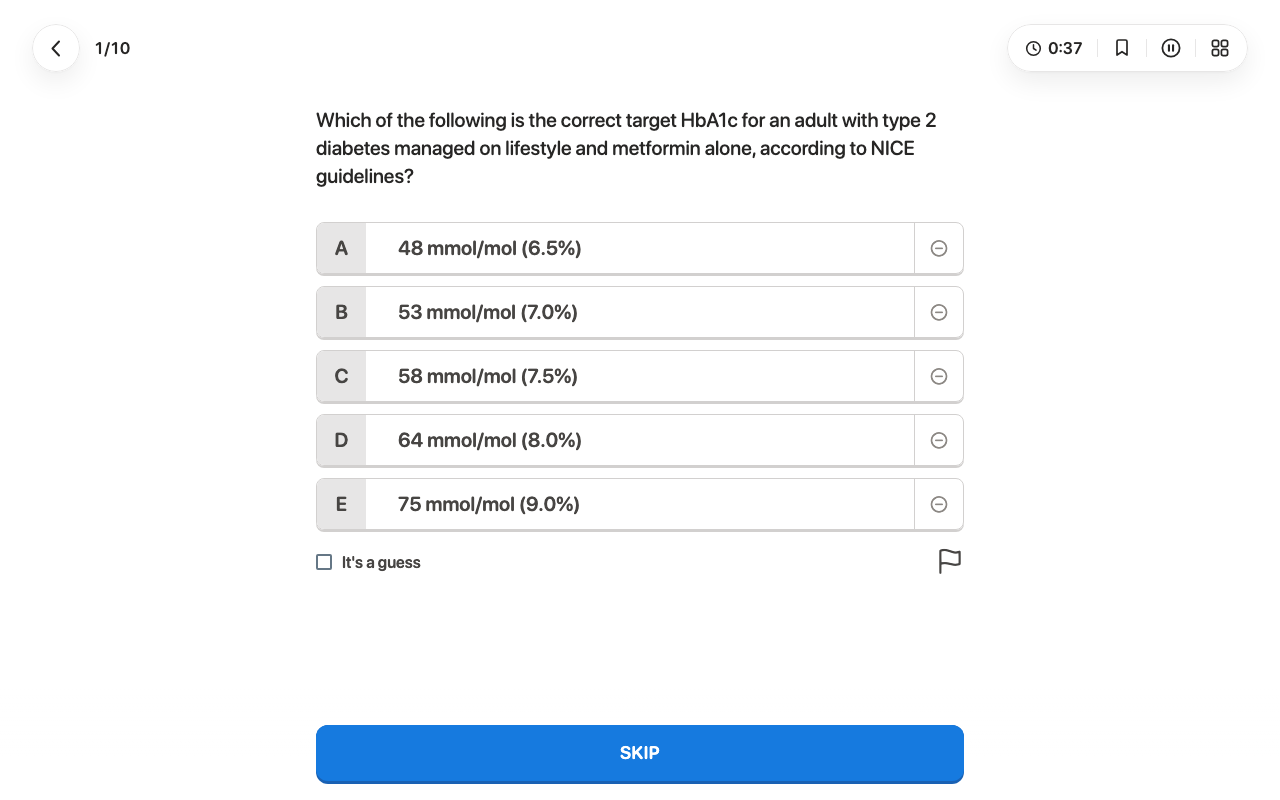
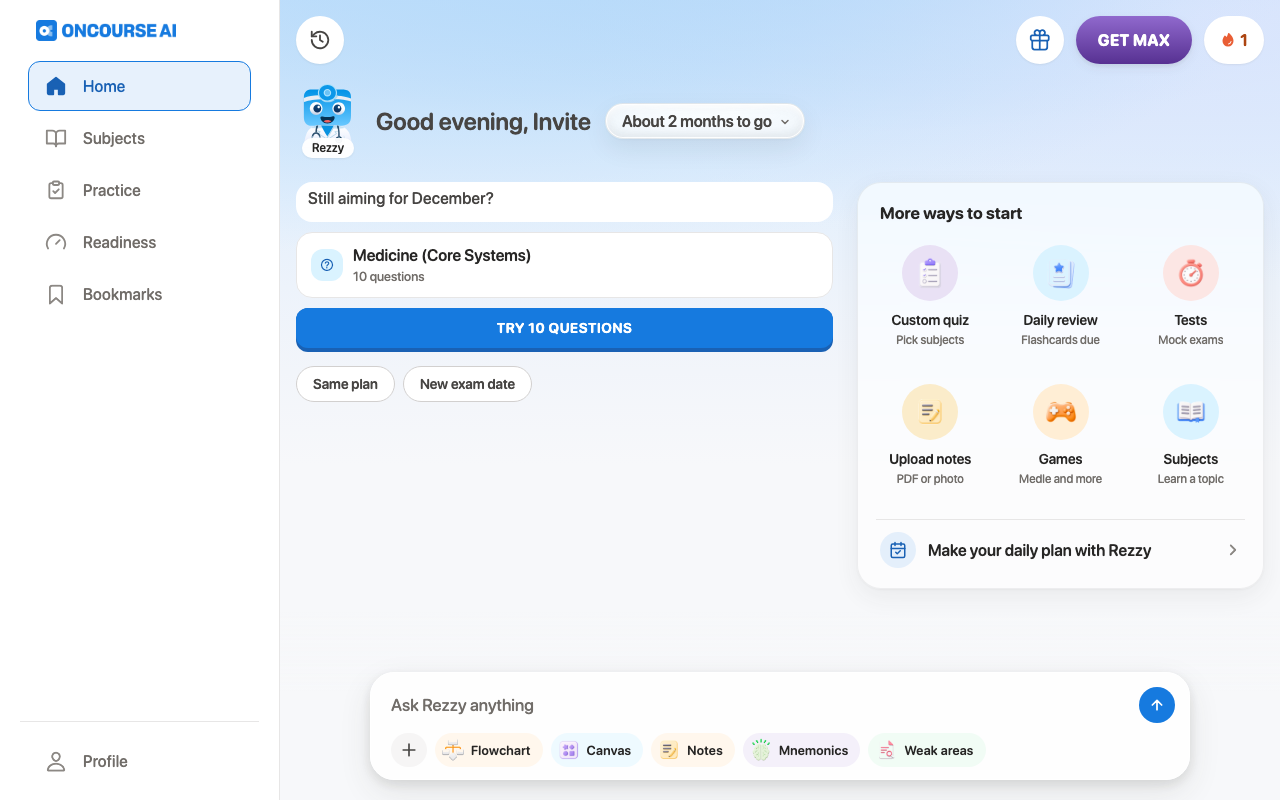
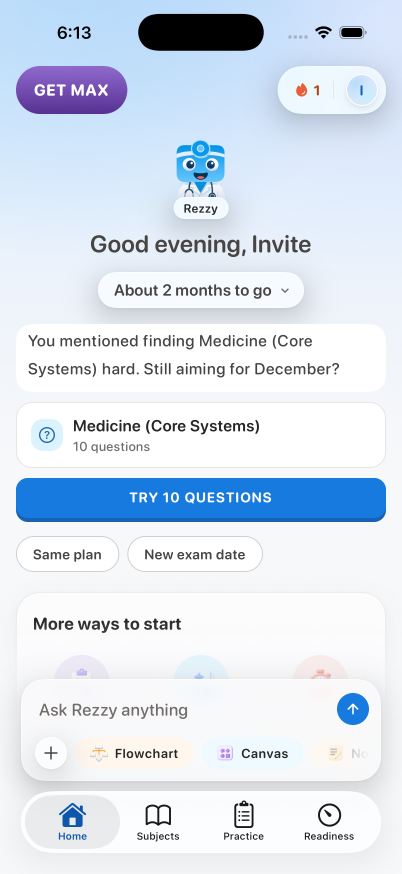
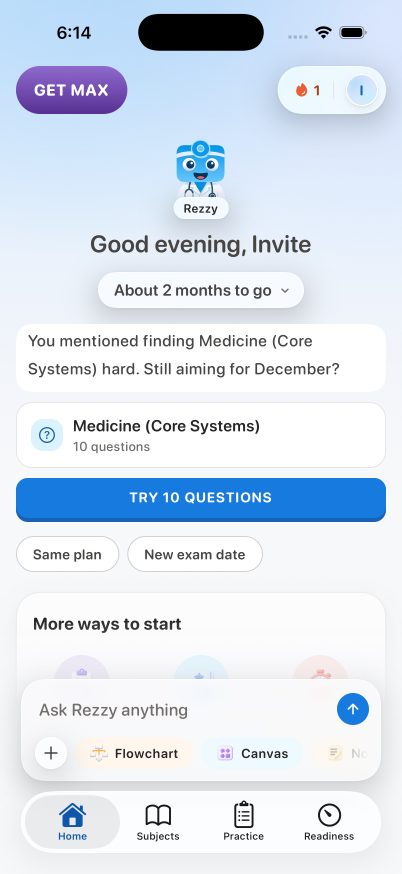
Still aiming for December? Either way, 10 Medicine (Core Systems) questions are ready.
Try 10 questions
Same planNew exam date
block: question_set · source: composed
Web: HomeWeb: after the first tapWeb: Home again after the tapiPhone: HomeiPhone: after the first tapiPhone: Home again after the tap
NCLEX-RN Rezzy
Learner state: a quiz four days ago, 3 misses; prefers flashcards
You have 12 flashcards due. Since you like flashcards, let's clear them out.
Review all 12
Something else
block: flashcard_peek · source: composed
Web: HomeWeb: after the first tapWeb: Home again after the tapiPhone: HomeiPhone: after the first tapiPhone: Home again after the tap
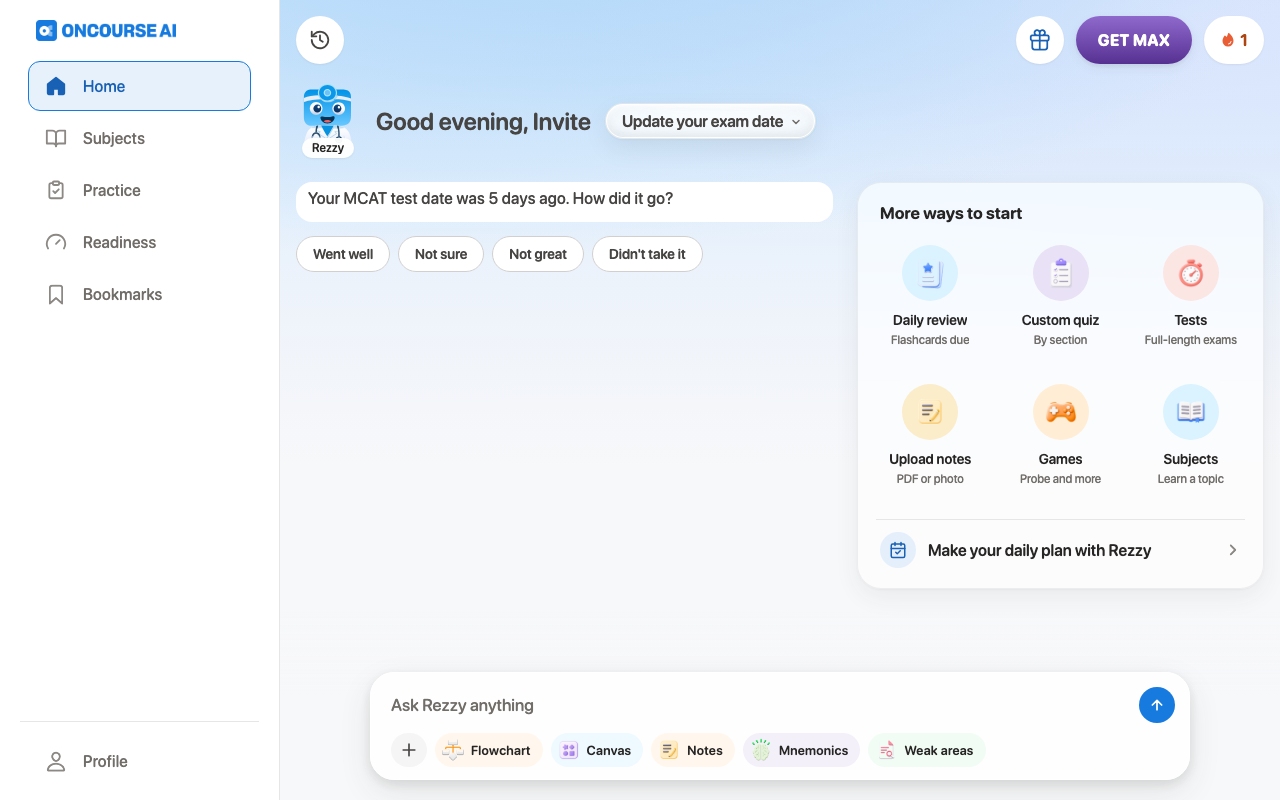
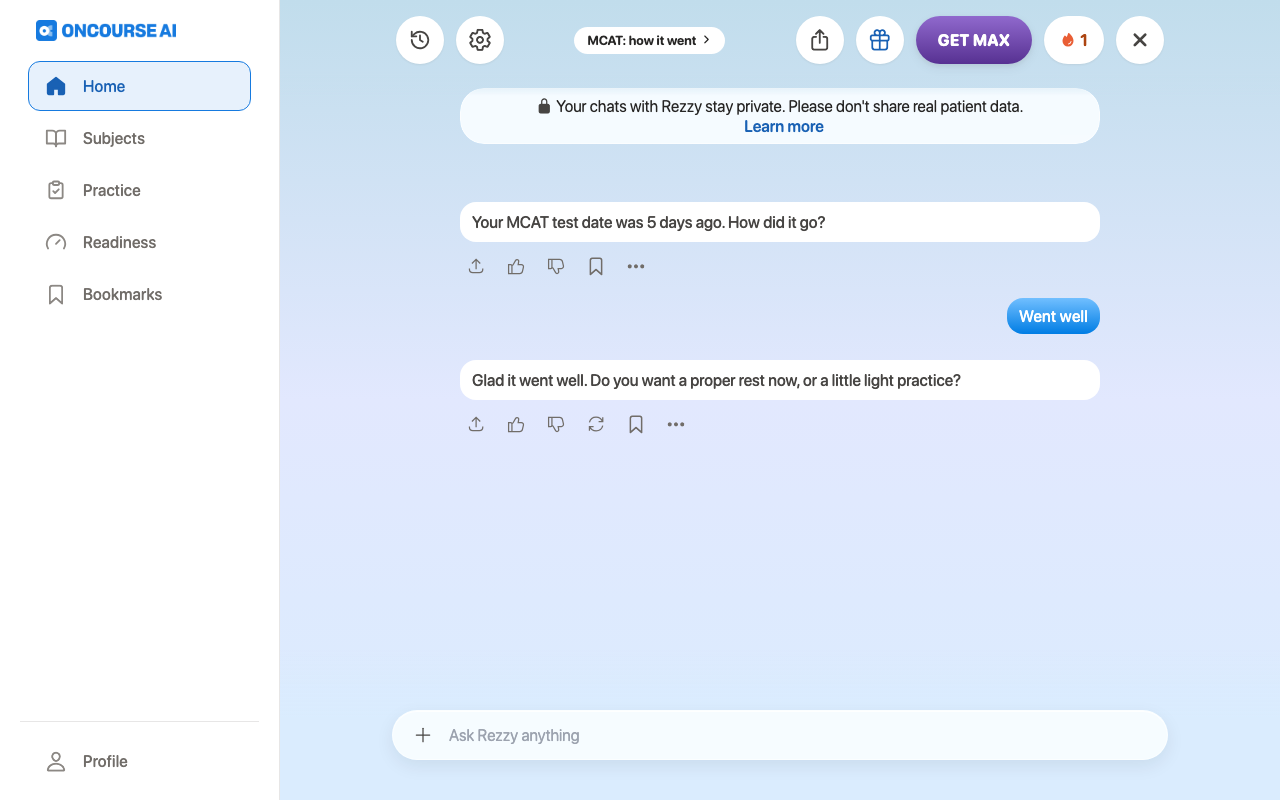
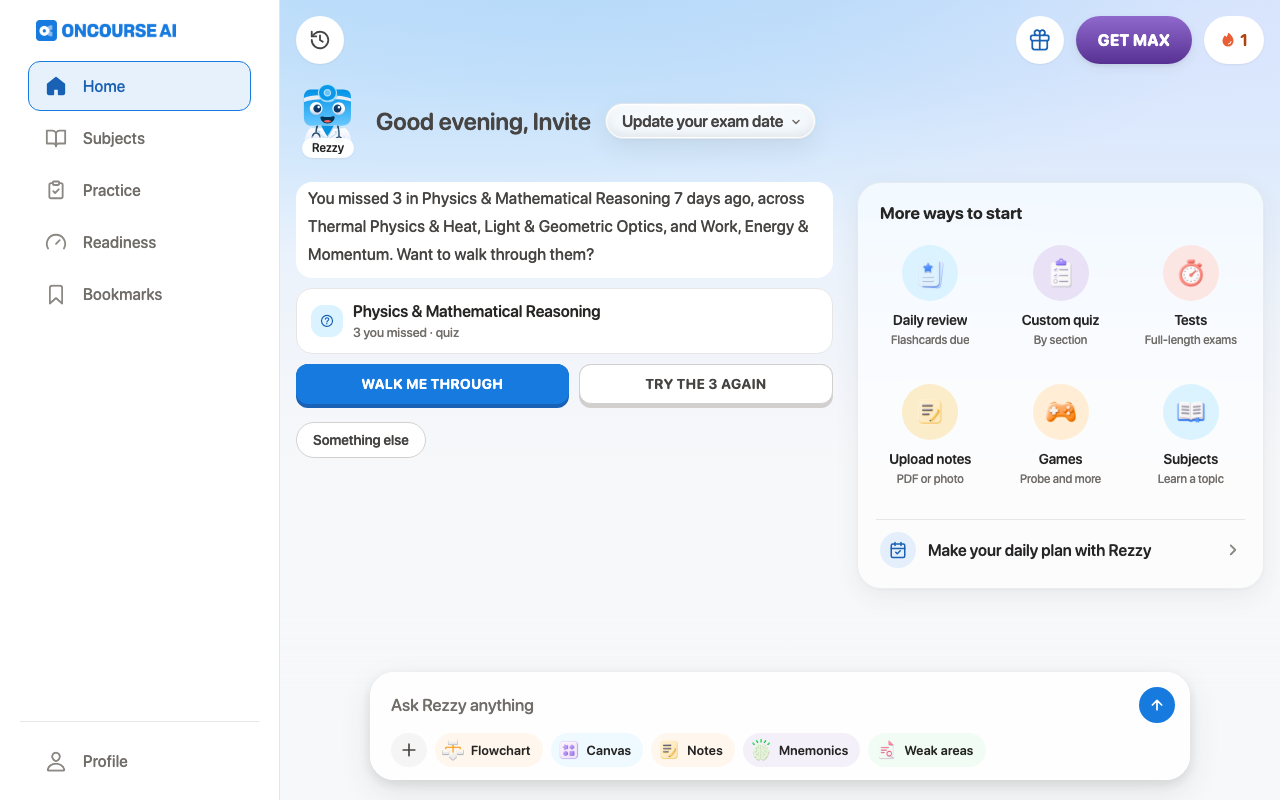
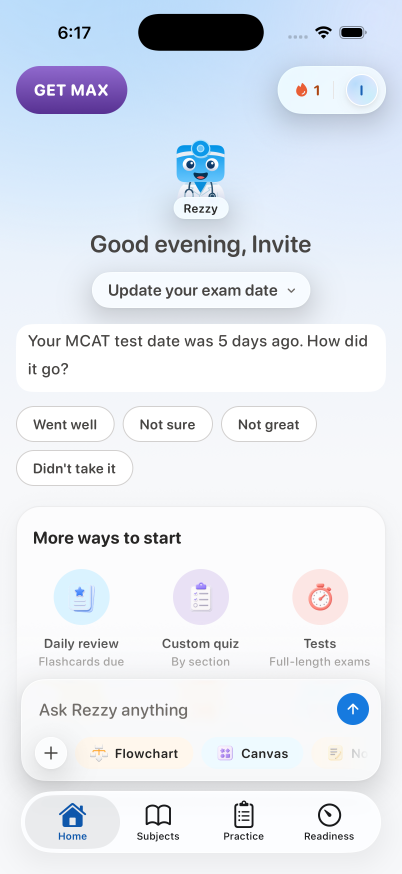
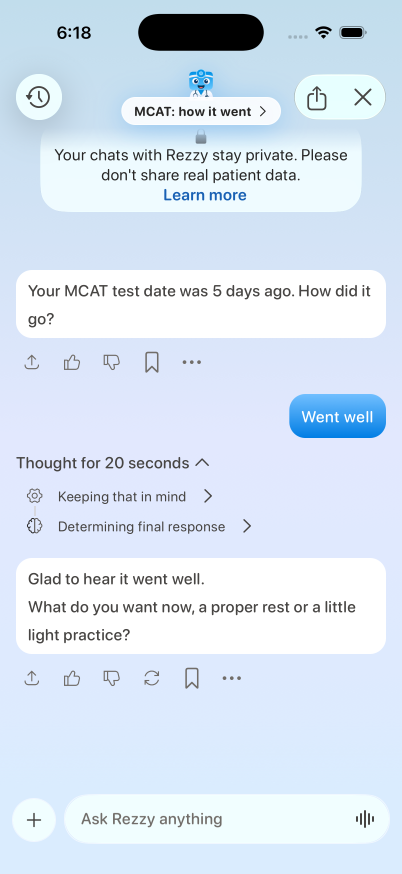
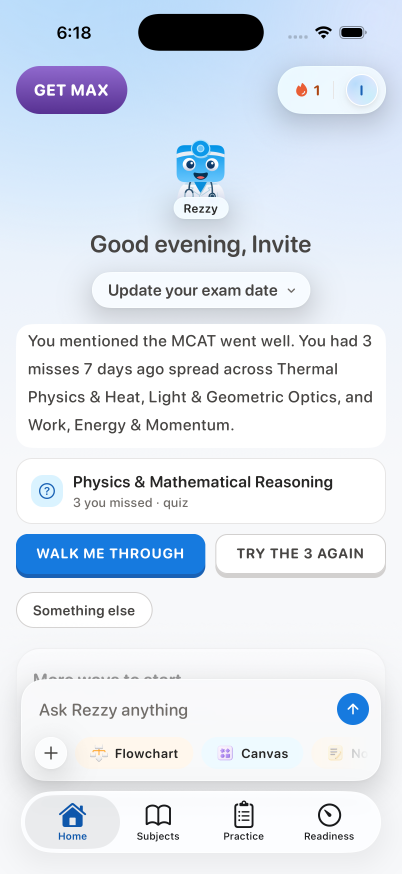
MCAT Rezzy
Learner state: exam date has just passed
How did your MCAT go on October 26?
Went wellNot sureNot greatDidn't take it
block: none · source: composed
Web: HomeWeb: after the first tapWeb: Home again after the tapiPhone: HomeiPhone: after the first tapiPhone: Home again after the tap
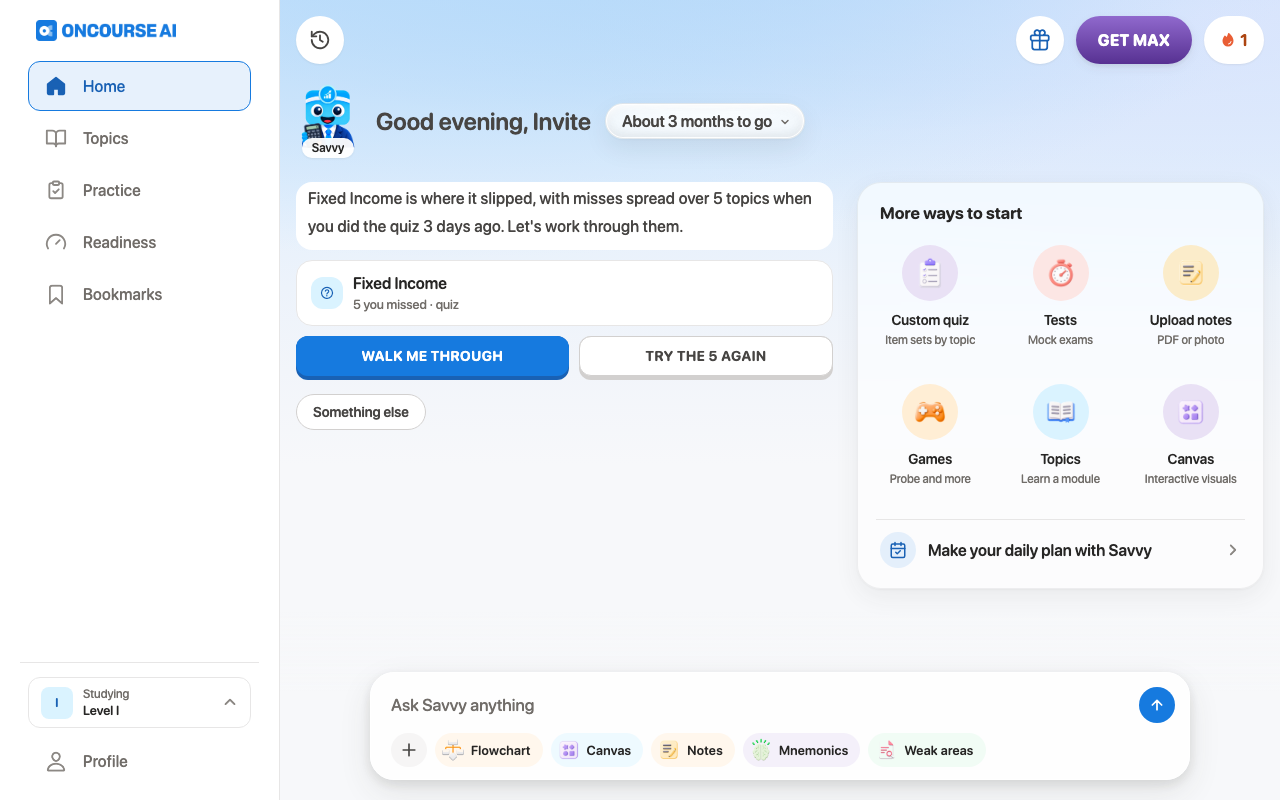
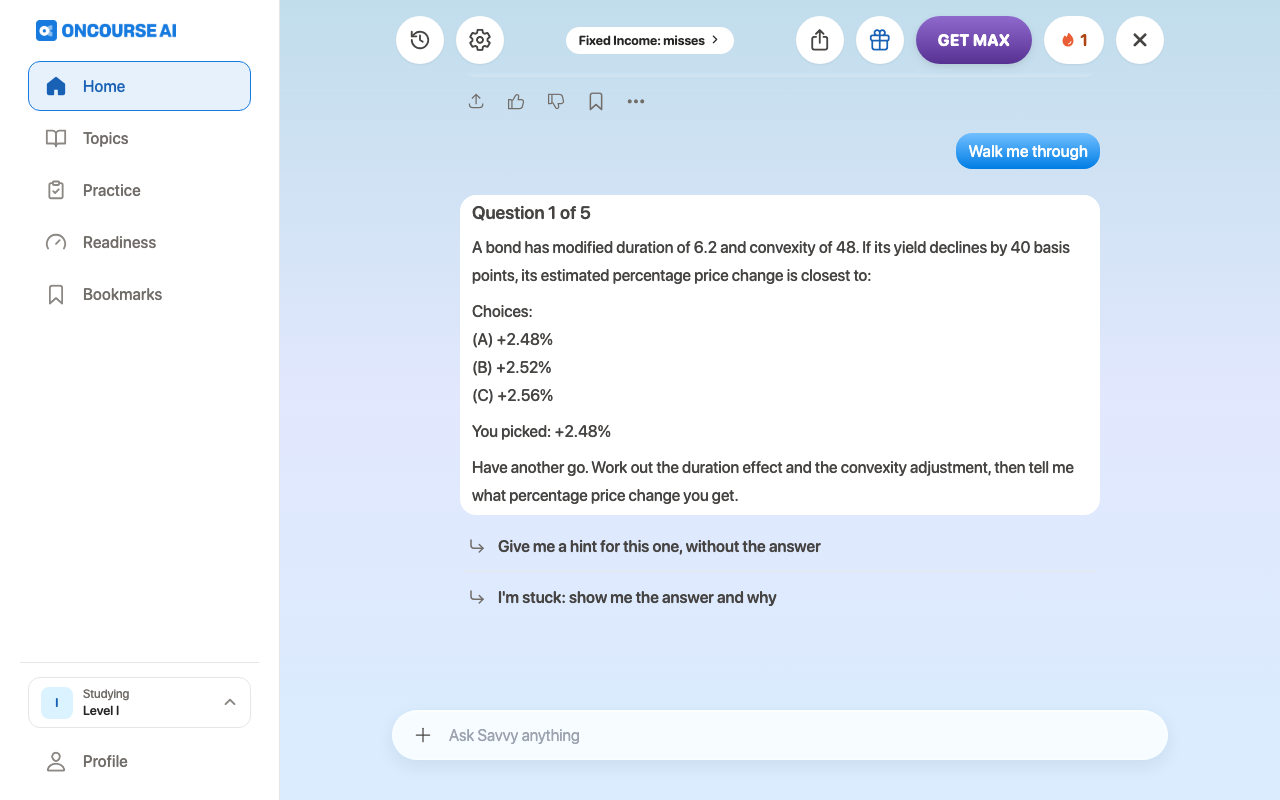
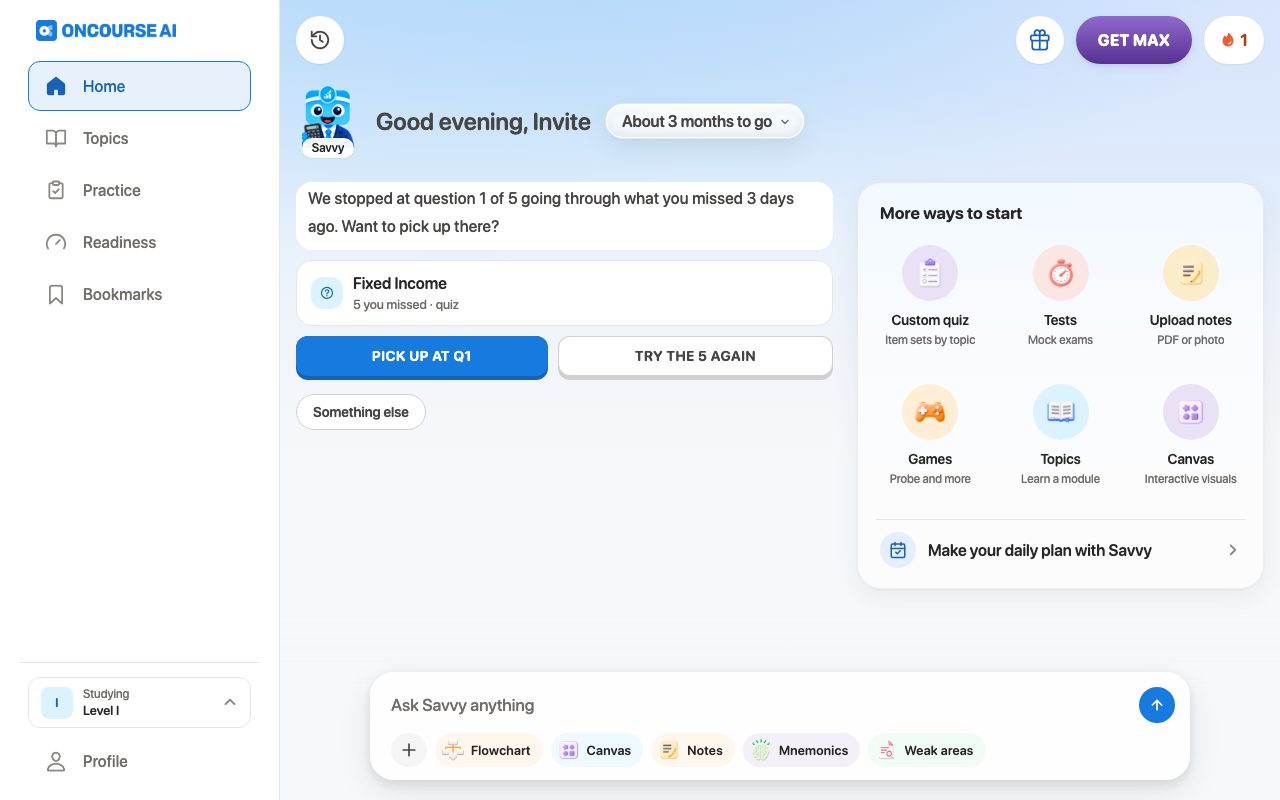
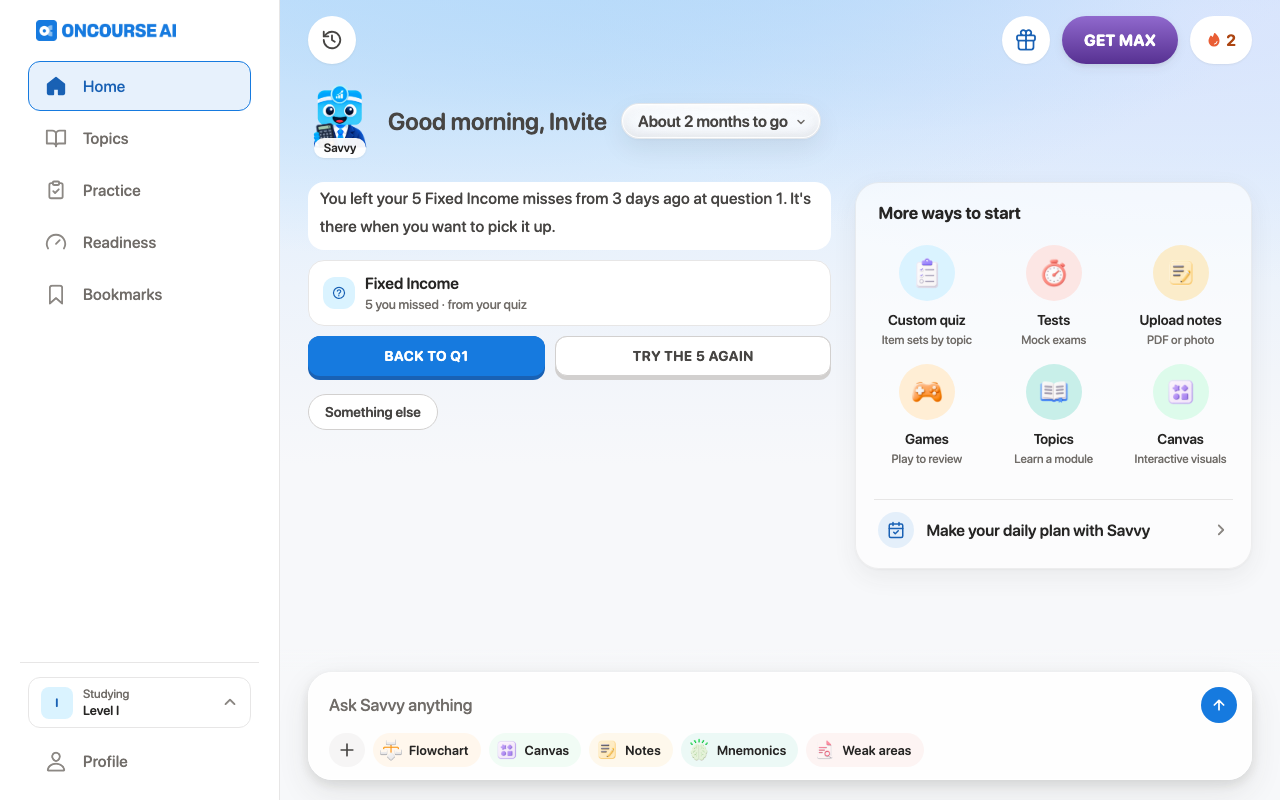
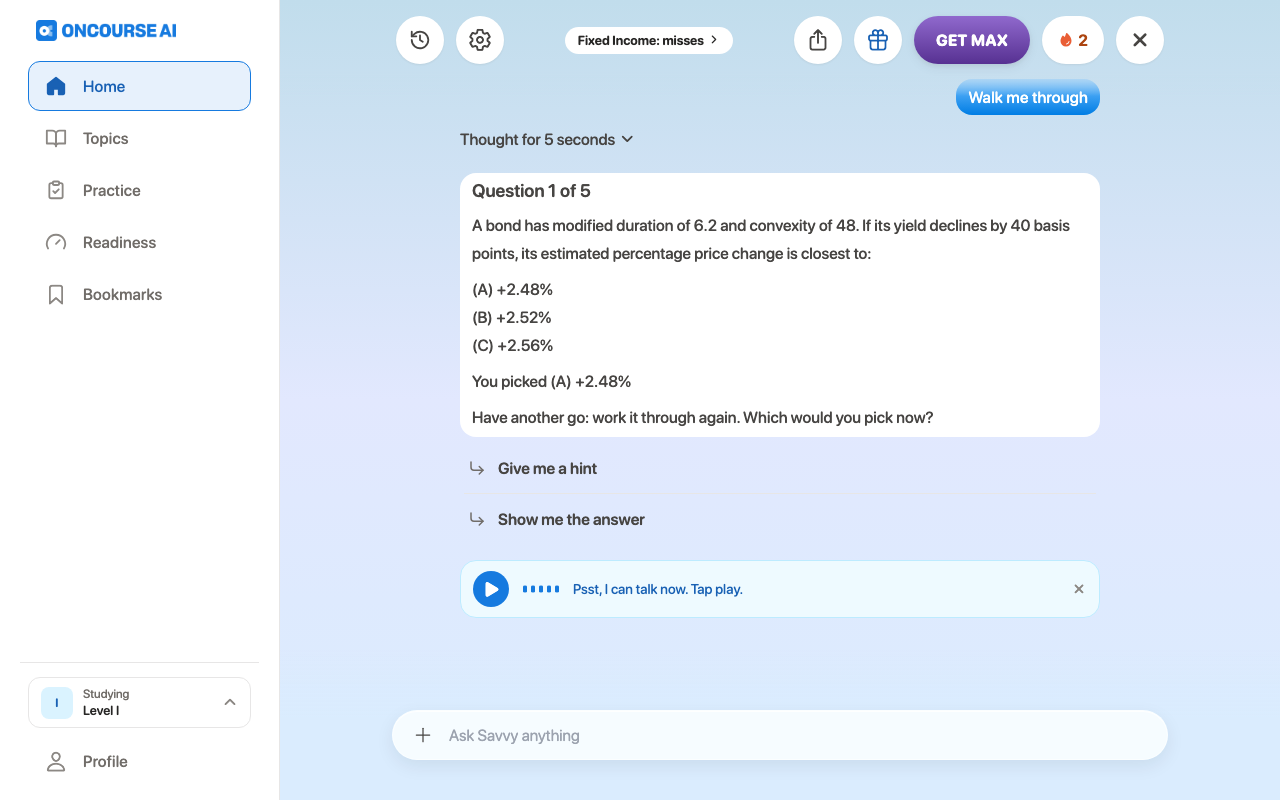
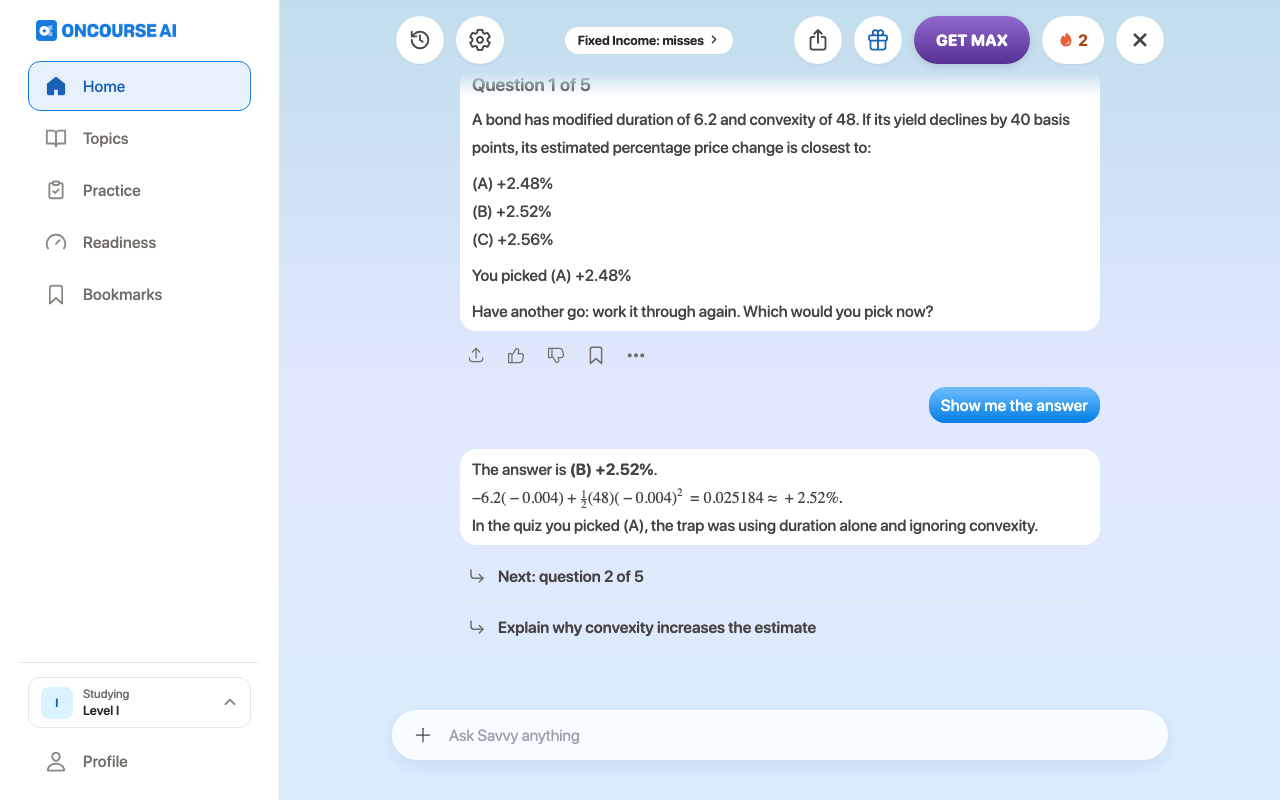
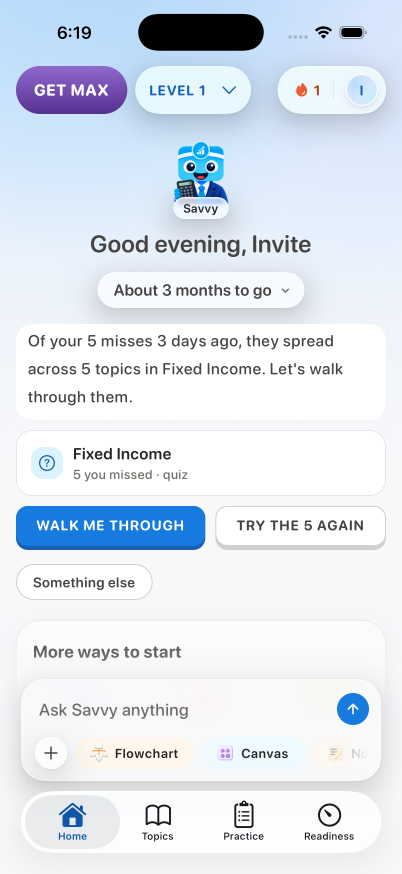
CFA Savvy
Learner state: a quiz three days ago, misses in Fixed Income
You missed 5 in your quiz 3 days ago, each in a different topic. I can walk you through them so you catch what slipped.
Walk me throughTry the 5 again
Something else
block: question_set · source: composed
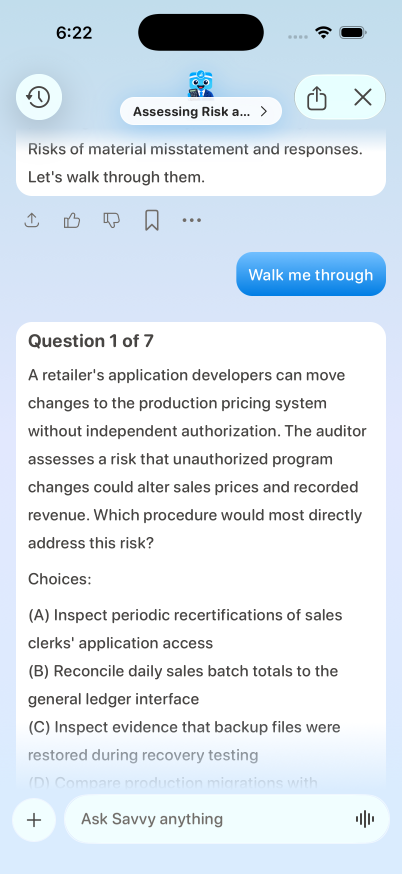
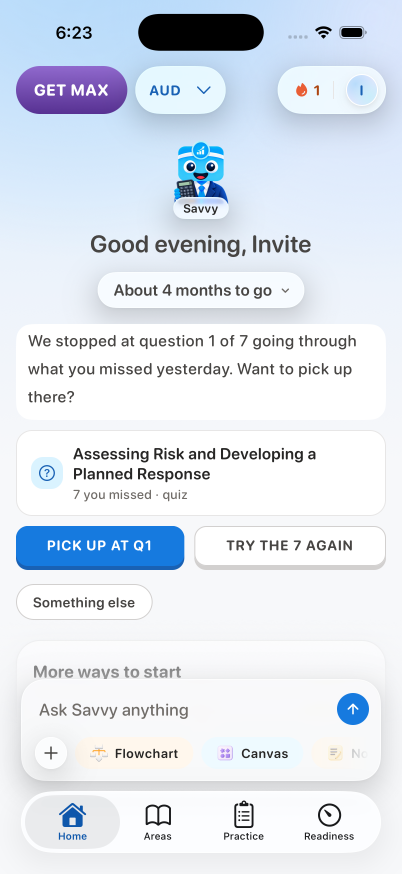
Web: HomeWeb: after the first tapWeb: Home again after the tapWeb: Home offering to pick the walkthrough upWeb: the walkthrough reopenedWeb: walkthrough after one answerWeb: Home after that answeriPhone: HomeiPhone: after the first tapiPhone: Home again after the tap
CPA Savvy
Learner state: a weak set yesterday, 7 misses
You missed 7 questions in yesterday's quiz, spread across 4 topics. Let's work through them together.
Walk me throughTry the 7 again
Something else
block: question_set · source: composed
Web: HomeWeb: after the first tapWeb: Home again after the tapWeb: Home offering to pick the walkthrough upWeb: the walkthrough reopenedWeb: walkthrough after one answerWeb: Home after that answeriPhone: HomeiPhone: after the first tapiPhone: Home again after the tap
LSAT Casey
Learner state: new, told the tutor about a worry (pacing)
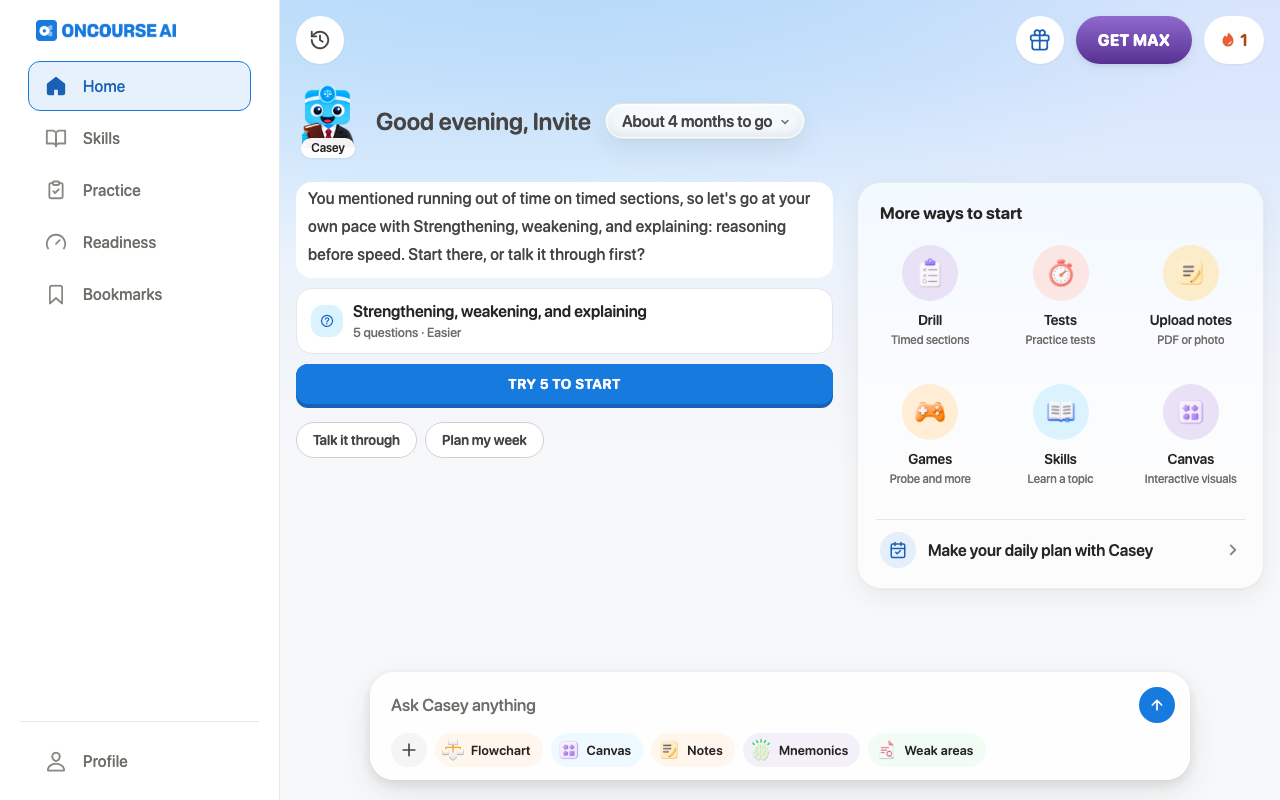
You mentioned running out of time on timed sections, so let's start with 5 easier questions to get the reasoning sure before speed. Start there, or talk it through first?
Try 5 to start
Talk it throughNot sure yet
block: question_set · source: composed
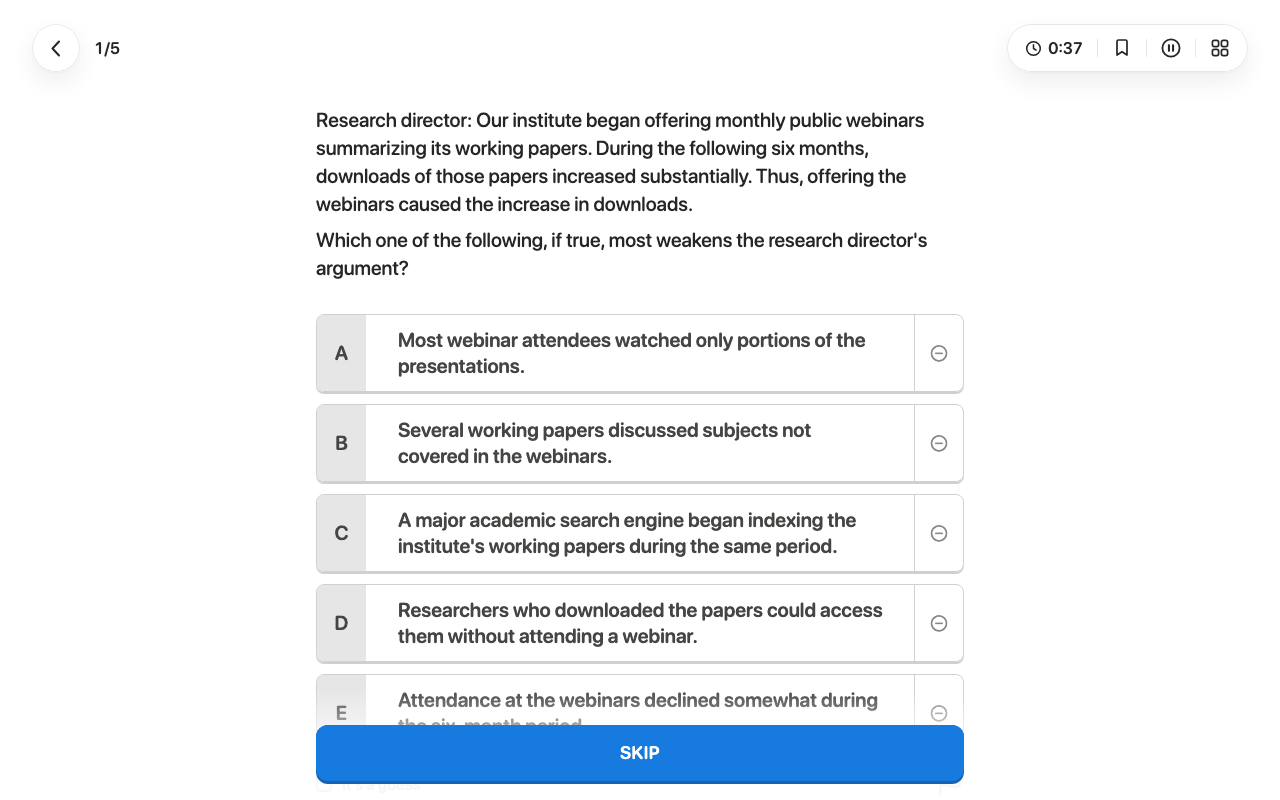
Web: HomeWeb: after the first tapWeb: Home again after the tapiPhone: HomeiPhone: after the first tapiPhone: Home again after the tap
Bar Exam Casey
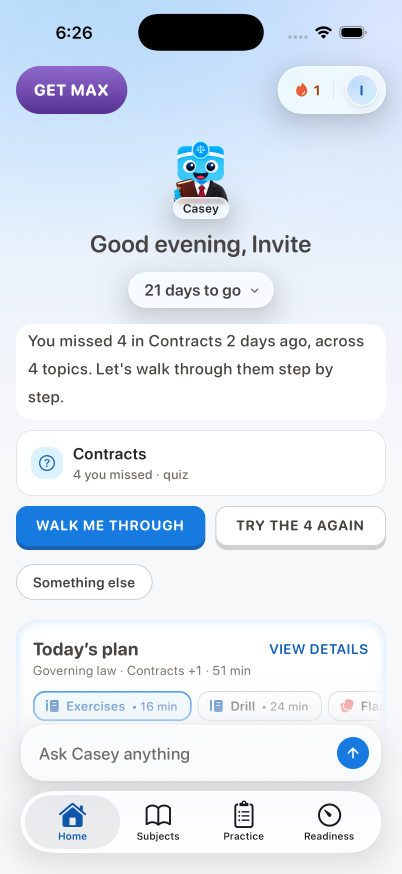
Learner state: retaker, misses in Contracts two days ago
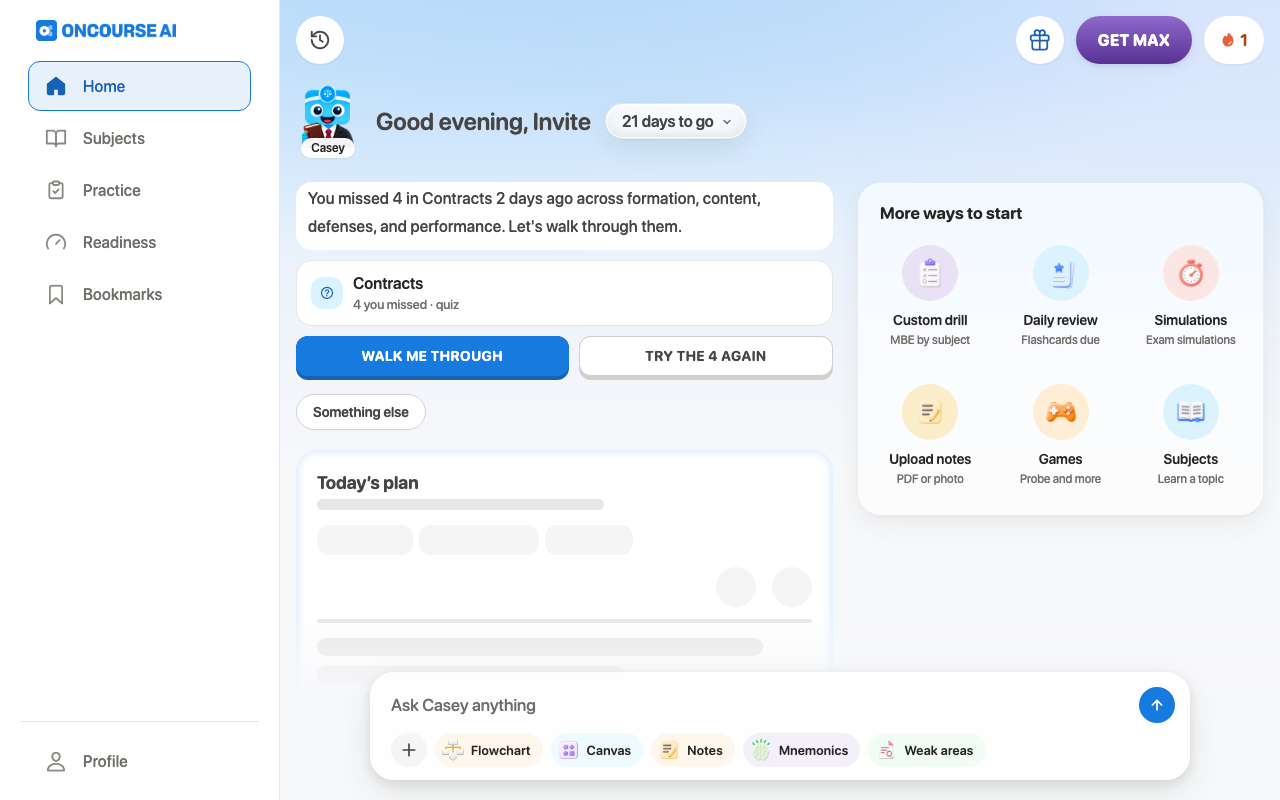
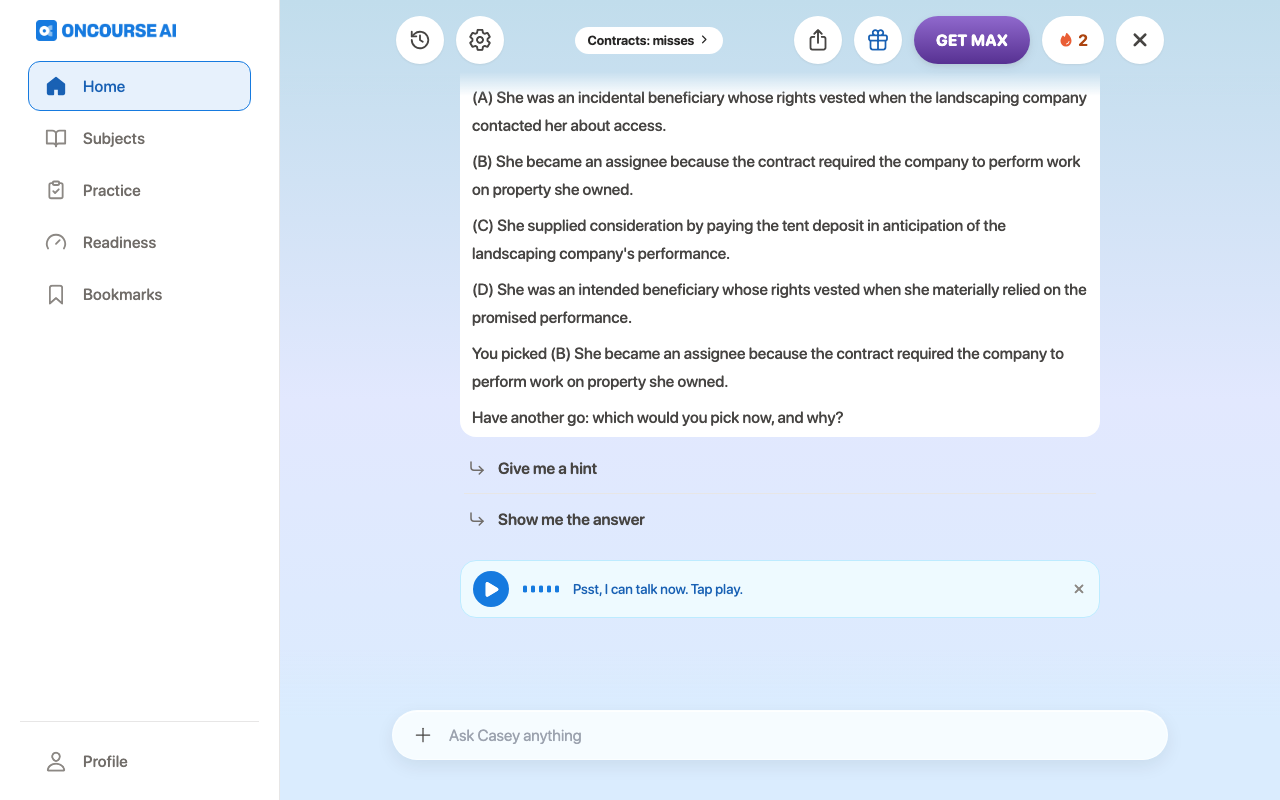
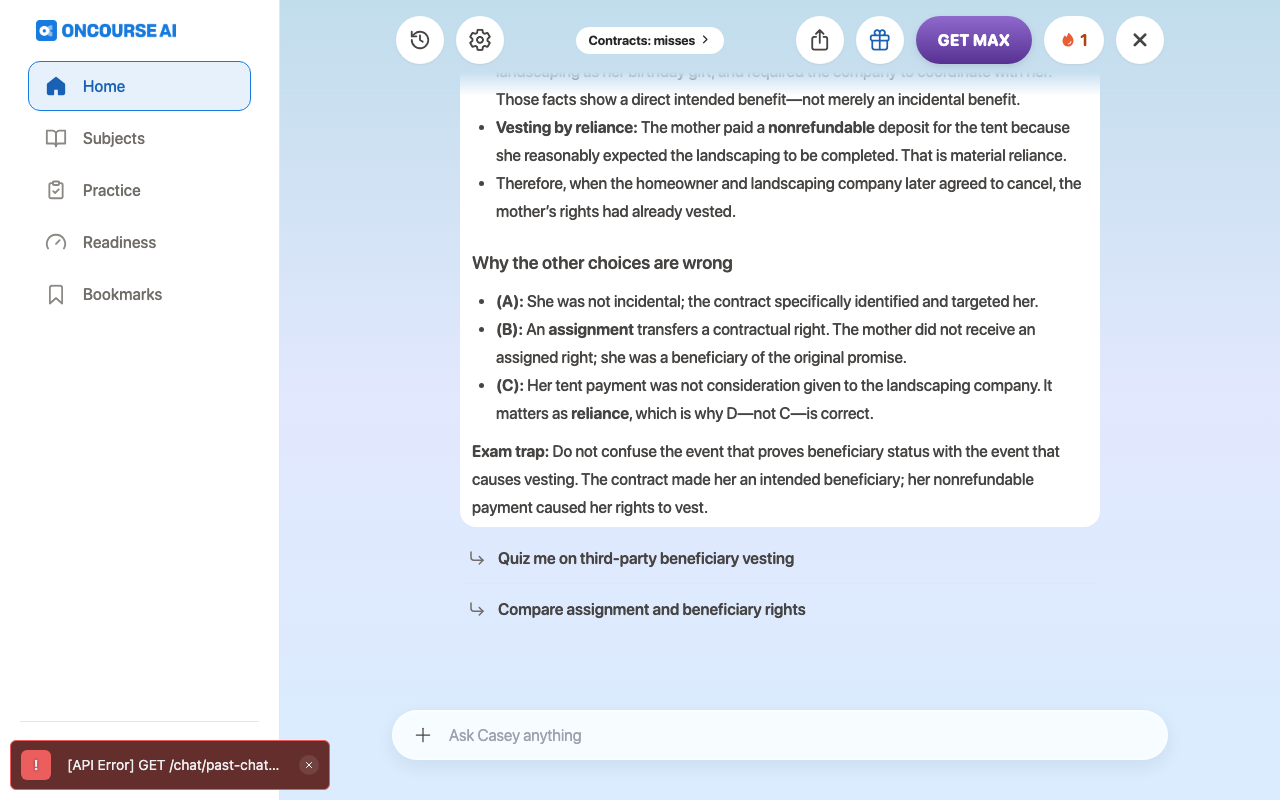
You missed 4 in your Contracts quiz 2 days ago, each in a different topic. Let's walk through them.
Walk me throughTry the 4 again
Something else
block: question_set · source: composed
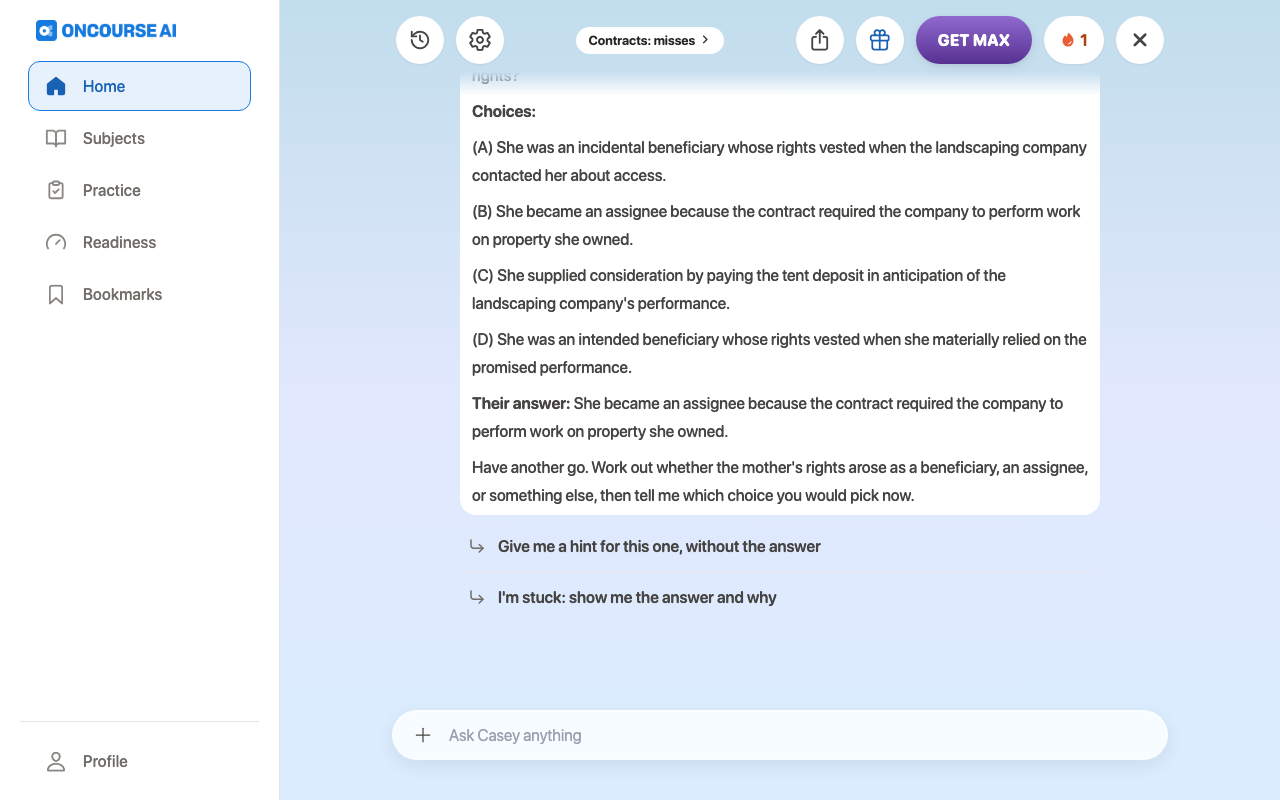
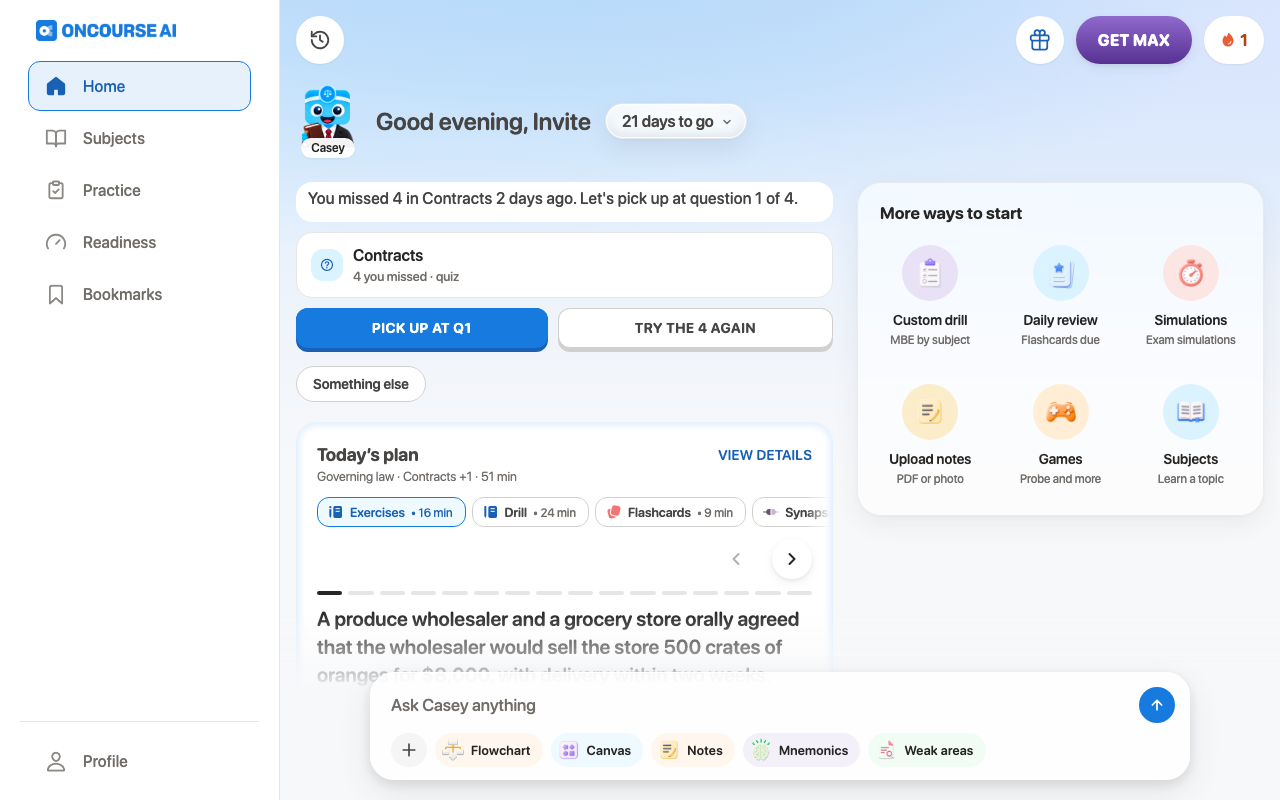
Web: HomeWeb: after the first tapWeb: Home again after the tapWeb: Home offering to pick the walkthrough upWeb: the walkthrough reopenedWeb: walkthrough after one answerWeb: Home after that answeriPhone: HomeiPhone: after the first tapiPhone: Home again after the tap
Tap-throughs
None this round.
No screen recordings for this final round. The Mac mini that runs the simulators ran out of memory three times on 31 October, and device work there was stopped, so the recordings were skipped. The card, tap and after shots for each course in the gallery above show where every tap lands, on web (api 9804566b) and the iPhone (api 388e38cb).
Real and mocked
Real: snapshot from staging data, offers with real ids, the model call through the api's provider setup, validation, fallback, caching, the act endpoint (test templates, flashcard ids, routes), the seeded chat with server-side turn instructions, analytics events. Seeded: the staging QA learners' history (wrong answers, lessons read, due cards, exam dates, memories) written by a staging-only script; flashcards are the course's own cards or built from the course's own plain MCQs, never another learner's. Not built: the Trigger.dev precompute (designed, not deployed), a persisted events table (Redis + PostHog only), games filtered by topic (games open on a subject where they can).
Known, outside this prototype
The exam date, pain points and study tools are read from the learner's profile, not per course, as exam pace and the week plan read them. A learner who switches courses keeps the first course's exam date until they change it. Everything else in the snapshot is limited to the active course (tested in invite.snapshot.unit.test.ts).
Days away and the streak count activity in any course: they describe the learner's rhythm, not course content.
Template quizzes have no timer, so no offer is timed (the exam-instinct offer is a plain quiz until the player has one).
Home's exam pill rounds an estimate to the nearest month ("About 1 month to go" at 20 days); the card no longer has its own countdown, and says only months for an estimate.
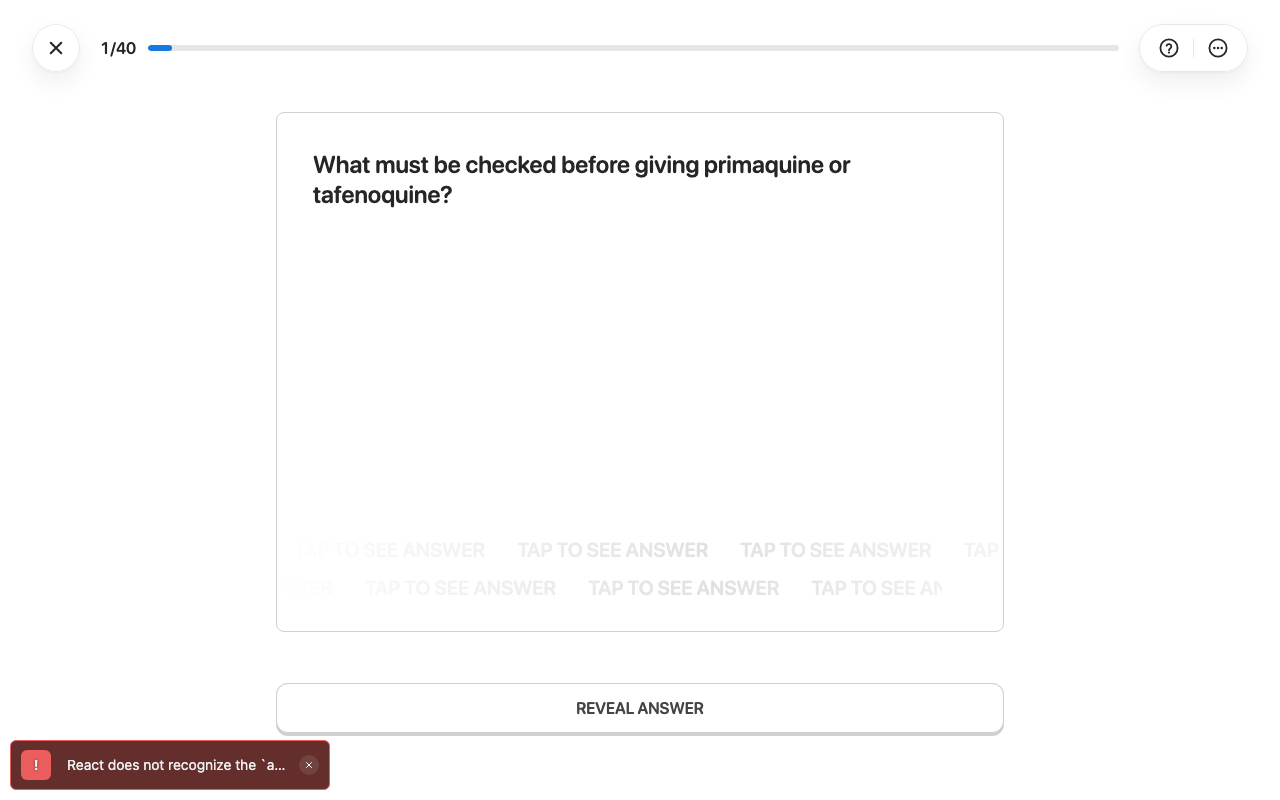
The review player shows a cloze card's raw braces; the card's peek blanks them.
The chat shows its Thinking trace and the voice teaser over a seeded chat, and dev builds show toasts over captures.
The first turn of "Make 10 cards" took about 28 s on staging (the model writes ten cards before saving them); the walkthrough's first turn is about 8 s. Streaming the cards one at a time is the fix, outside this prototype.
The api exits on an uncaught error from a chat message with a non-UUID id (an adjacent bug, reported separately).
Past chats are polled while a reply streams.
Analytics set nav: "approach_b" literally, like the rest of approach-B Home; the card renders only there.
A topic quiz trusts the bank's topic tags. On staging some are loose: US Medical PG's Pharmacology "Antimicrobials" holds 373 questions, including an alprazolam question and a fracture case, so a quiz on it can open off topic (prod not checked).
Open questions
The next step: should the composer return structured slots (which offer, which count, which subject) that the server words, in place of free text checked by a growing list of regex rules? Every council since round 8 points here.
Topic and lesson names are grounded by the prompt only; should the validator check every named topic against the snapshot?
Precompute on events (a set submitted, the day rolling over) in Trigger.dev so the first open is never inline?
A timer for template quizzes, so an exam-instinct offer can be timed.
Where the card's taps and ignores should live long term (Redis and PostHog today, no table).
Whether to let the card replace the day's prompts for own-schedule learners, or always sit above them.
How often a learner should see a check-in (exam went, feeling) before it reads as nagging.
The exam date and pain points live on the profile, not the course: should a course switch ask for the new exam date (exam pace and the week plan share this)?
Should the eval judge run on a sample of live cards too (about $0.0009 a card), feeding failures back into the golden set?
Council score history
Two councils (Claude Opus 5.5 and GPT-6.1-Sol), each with learner reviewers for a Rezzy, a Savvy and a Casey course and an engineering reviewer, fresh every round. The bar was 9/10 on both axes from both councils; the loop stopped after round 11 short of it.
Round
Opus learner
Opus engineer
Sol learner
Sol engineer
Top finding
1
2026-10-30
6 (7/7/6)
6
6 (7/8/6)
5
api 21ee70af, app d62e23e82, web captures
Numbers on cards weren't all grounded in the data, and a late model could show a different fallback on every open.
2
2026-10-30
6 (6/7/7)
7
7 (7/8/7)
6
api 94b8087a, app bc38da8ba, web captures (all 9 re-seeded, one run)
A tap didn't always open what the button promised (quiz fills short of the count, due-card counts that drifted).
3
2026-10-30
6 (6/7/7)
7
7 (7/7/8)
7
api 2393ae51, app e69fdddaa, web + iPhone captures (iPhone composes after an api restart)
A quiz "on a lesson" opened loosely tagged questions; counts on buttons weren't exact against the bank.
4
2026-10-30
7 (7/7/8)
7
8 (8/8/9)
6
api 6e39192d, app 90d4750dc, web + iPhone captures, output judge on the 68-learner eval
A tap on a card replaced while it was on screen could fail; quiz resizing rewrote unrelated facts.
5
2026-10-30
7 (7/7/7)
7
8 (8.5/8/8)
7
api d1fef14b, web + iPhone captures, eval run8
Check-in chips and timing ("results out yet?" five days after the MCAT); flashcard learners offered the wrong step.
6
2026-10-30
7 (7/7/7)
7
8 (8/8/8)
7
web + iPhone captures, dealt records per set and lesson
Opening a walkthrough marked the whole set done, so Home moved on before the learner finished.
7
2026-10-30
6 (6/7/8)
6
7 (8/7/9)
6
api ac1f2700, web + iPhone captures, NEET PG and Bar answer shots
After "Went well" Home pushed pre-exam misses; the walkthrough's state lived in the model's memory of the first turn.
8
2026-10-30
6 (6/7/7)
7
7 (7/8/8)
7
api 2266d7eb, app 042e715fe, walkthrough state in Postgres, rules resume card; web + iPhone + answer shots
The walkthrough's try line read as a calculation on recall questions; one-miss topics were named as where the misses gathered.
9
2026-10-30
7 (7/7/8)
7
8 (8/8.5/8.5)
7.5
api 6ab52076, app 042e715fe, walk commits on delivery, no card after "went well", no-verdict reveal; web + iPhone + answer shots
Counts the validator didn't tie to a topic or deck ("15 on Enzyme Kinetics" when 2 were); Home pushed practice right after "Went well".
10
2026-10-31
7 (7/7/7)
7
7 (7/7/8)
7
api bdbc5f53, app c1c844b4c, full 162-learner eval, quiet Home after the exam, lesson in the check's turn, stricter validator; web + iPhone + 4 answer runs
The walkthrough's last step never saved (it ended on a tool call); copy the regex validator let through; first-try validity falling as checks grew.
11
2026-10-31
7 (7/8/7)
7
8 (8/8/8)
7.5
api 9804566b (iPhone run on 388e38cb), app c1c844b4c, walkthrough end saved, narrower walkthrough routing, more validator checks, rules card one idea; web + iPhone + 4 answer runs. Last round: the owner stopped the loop here (option B)
The validator is a growing list of regex checks over free text: move the model to structured slots the server words.